Why Predictive Maintenance Starts with Connected Devices
IoT predictive maintenance only works when devices capture clean, connected data. Learn what to instrument, how to integrate it, and how to measure ROI.
 William Smith
Most predictive maintenance programs do not fail because of a weak model. They fail because the machine never sent usable data in the first place.
That gap costs a lot. Siemens' True Cost of Downtime 2024 report estimates that unplanned downtime costs the world's 500 biggest companies about $1.4 trillion a year, or 11% of revenue. The same report shows that 87% of large manufacturers collect some machine health data, but only half capture at least one of the three signals that matter most: current, vibration, and temperature. Nearly three-quarters still use factory historians. The report says these are increasingly seen as legacy technology because they lack the rich data that effective predictive maintenance needs.
The average large plant in the survey still loses 326 hours a year to unplanned stoppages. Buying analytics software will not close that gap. Reliable, connected devices will.
This guide explains what those devices must deliver, how to link their data to service workflows in CRM and field service platforms, and how to measure the return. It also covers what to ask an IoT solution provider before you commit a budget.
Predictive Maintenance Is a Data Problem Before It Is an AI Problem
Teams often buy analytics software first and think about sensors second. That order wastes months.
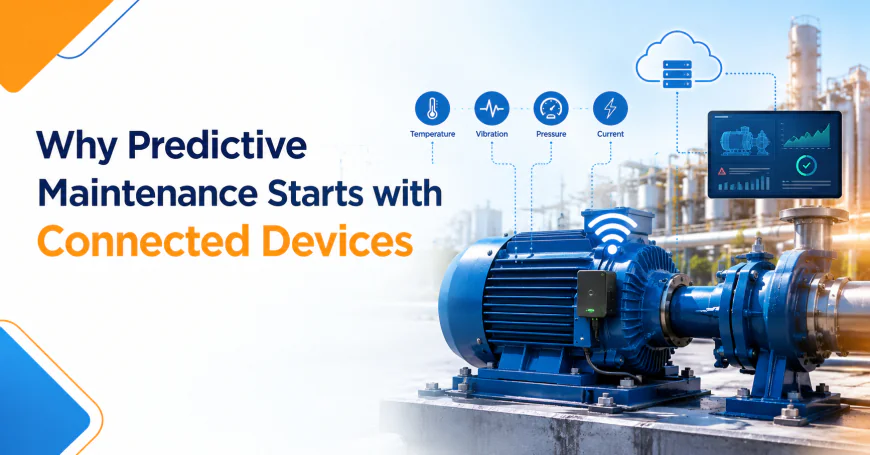
A model learns from patterns in equipment behavior. It cannot learn from signals it never received. A pump that reports only "running" or "stopped" gives the model nothing to work with. A pump that reports vibration, motor current, and bearing temperature every few seconds gives it a health fingerprint.
Connected devices must deliver three things.
-
Coverage. Instrument the assets that cost you most when they fail, not every asset on site.
-
Quality. Use the right sampling rate, stable timestamps, and calibrated sensors.
-
Context. Tie every reading to an asset ID, a location, a production run, and a maintenance history.
Miss one of these and the output turns into noise. Siemens makes a related point. Effective programs draw on maintenance records, operational systems, and manufacturing execution systems alongside sensor data.
What Connected Devices Include on the Plant Floor
A connected device is more than a sensor with a radio. It is a chain of parts, and the weakest link sets the quality of your data.
-
Sensors capture physical signals such as vibration, temperature, pressure, and current.
-
Gateways or edge controllers collect readings, translate protocols, and filter noise.
-
Connectivity carries the data over wired Ethernet, Wi-Fi, cellular, or LoRaWAN, depending on plant layout.
-
A platform layer stores time-series data, manages device identity, and pushes firmware updates.
-
Applications turn alerts into work orders, dashboards, and customer notifications.
Older machines add a wrinkle. Plenty of plants run equipment built before network standards existed. Retrofit sensors that clamp onto motors and bearings solve this without replacing the asset. Protocols such as OPC UA and MQTT then move the data into modern systems. Cloud providers follow the same pattern. AWS, for example, pairs device connectivity and remote device management with event monitoring and machine learning services.
Choosing the Right Signals for Each Asset
More sensors do not mean better predictions. Each asset class fails in specific ways, and each failure leaves a specific trace.
|
Asset |
Common failure |
Signals worth capturing |
|
Motors and pumps |
Bearing wear, misalignment, imbalance |
Vibration, motor current, temperature |
|
Compressors |
Valve wear, overheating, leaks |
Pressure, temperature, vibration |
|
Gearboxes and conveyors |
Gear wear, lubrication loss |
Vibration, oil temperature, load |
|
CNC machines |
Spindle wear, tool breakage |
Spindle load, vibration, acoustic signals |
|
Refrigeration units |
Refrigerant loss, compressor fatigue |
Temperature, pressure, energy draw |
Start with the signals in the table and add more only after the first model shows what it lacks. Refrigeration deserves special care in regulated industries. Pharmaceutical makers, for instance, connect refrigeration sensors to predictive maintenance software to detect signs of equipment malfunction.
Where Predictive Programs Break Before the Model Runs
Stalled projects usually trip over the same data problems. Catching them early saves months of rework.
-
Timestamps drift across devices, so events cannot be lined up.
-
Sampling rates run too slow to catch fast vibration signatures.
-
No failure history exists, so the model has nothing to learn from.
-
Alerts fire too often, and technicians stop trusting them.
-
Data sits in a historian that no other system reads.
Siemens found another pressure point. Plants now take 81 minutes on average to restart after a stoppage, up from 49 minutes five years ago. The report ties this to lost skilled labor, slower parts delivery, and the fact that monitoring now catches easy problems while harder ones remain. So each alert must be specific enough that a less experienced technician can act on it.
Edge, Gateway, or Cloud for Processing
Where you process data changes cost, latency, and reliability. Each layer has a job.
Vibration analysis produces high-frequency data. Sending raw waveforms from hundreds of machines to the cloud burns bandwidth and adds delay. Most plants do better with a hybrid design.
-
Edge devices calculate summary features such as RMS vibration, peak frequency, and temperature trends. They also trigger local alarms when a limit trips.
-
Gateways buffer data when the network drops and translate between industrial protocols.
-
The cloud stores history, trains fleet-wide models, and serves dashboards to people across sites.
This split keeps the plant running if the wide-area link fails. It also cuts data volume, which lowers storage and transfer costs. Sites with patchy connectivity benefit most, because the edge layer keeps collecting and forwards the backlog once the link returns.
Connecting Machine Data to Work Orders and Revenue
An alert that never reaches a technician saves nothing. The last mile between device and workflow decides the return.
Salesforce documents this flow in its own materials. Real-time asset data feeds AI models in Data Cloud, which automatically generate work orders and schedule maintenance in Salesforce Field Service before issues occur. Salesforce also describes an Asset Service Prediction capability that analyzes historical service data to forecast when and why assets might fail. Some Salesforce pages now label the data layer Data 360.
The value reaches beyond the maintenance team. For equipment makers and service providers, the same data supports revenue operations.
-
Service contracts can reflect actual asset condition and usage instead of flat estimates.
-
Warranty decisions rest on device logs, not disputed reports.
-
Renewal talks open with uptime data the customer already recognizes.
-
Parts and technician planning improve when failures are forecast, not discovered.
None of this works without clean identity mapping. The device ID in your IoT platform must match the asset record in the CRM. Teams underestimate this task more than any other. Fix it in the pilot, before you scale.
A Real Example from Steel Manufacturing
BlueScope offers a useful reference because its program started small and grew. The steel producer is based in Australia and runs plants across New Zealand, China, Southeast Asia, and North America.
Its pilot began in 2022 at the Springhill Works site in Port Kembla. Over three years, the company avoided about 2,000 hours of unplanned downtime, including more than 1,200 hours in Australia and over 750 across sites in New Zealand and Southeast Asia. Siemens also reports that the program helped prevent 53 complete process interruptions. The platform, Siemens Senseye, combines real-time machine data with AI-driven analytics to detect early signs of equipment degradation.
Two lessons apply to any enterprise. A single-site pilot produced proof that justified expansion. And the gains came from catching degradation before lines stopped, which depends on continuous machine data.
Siemens published these results and did not disclose dollar savings. Treat them as directional. Convert the hours to money using your own cost per hour of downtime.
How to Measure the Return
Executives fund predictive maintenance when the math is clear. Build the case from four lines.
-
Avoided downtime value equals hours avoided multiplied by your cost per hour.
-
Maintenance savings come from fewer emergency repairs, less over-maintenance, and smaller spare-parts stock.
-
Labor productivity counts technician hours redirected to planned work.
-
Program cost covers sensors, connectivity, platform fees, integration, and support.
Vendor data gives a sense of scale. Siemens reports results from its own Senseye deployments, including a 50% reduction in unplanned machine downtime, a 40% reduction in maintenance costs, a 55% increase in maintenance staff productivity, and an 85% improvement in downtime forecasting accuracy. It also says large manufacturers recouped their investment within three months. Treat these figures as a ceiling, since the vendor measured its own clients.
Here is an illustration with placeholder numbers. A plant loses 326 hours a year, matching the Siemens average, and each hour costs $100,000. A conservative 25% reduction saves about 81 hours, or roughly $8 million. Replace both inputs with your own figures before you take the case to finance.
A Four-Phase Rollout
A phased plan keeps risk low and evidence high. Each phase should end with a decision, not a report.
-
Rank assets by cost of failure. Pick 10 to 20 assets where a breakdown stops production or breaks a service commitment.
-
Instrument and baseline. Install sensors and collect several weeks of normal operating data before you set alert thresholds.
-
Integrate with workflows. Map device IDs to asset records and route alerts into work orders with clear next steps.
-
Review and expand. Compare each alert with what technicians found, tune thresholds, then add assets and sites.
Aim to show a measurable result within one or two quarters. If the pilot cannot show one, fix the data pipeline before you buy more sensors.
Considerations for the USA and India
Both markets share the same physics but face different pressures. Multi-site companies need to plan for both.
In the United States, the labor gap shapes the case. Siemens links longer recovery times partly to skilled maintenance workers lost during the post-Covid resignation wave. It also notes that predictive strategies help firms cope as experienced engineers retire. Connected devices widen the attack surface, so security needs a place in the design from day one. The IEC 62443 series is the usual reference for industrial cybersecurity.
In India, adoption is accelerating. P&S Intelligence values the Indian predictive maintenance market at USD 614.0 million in 2025, growing at a 30.8% CAGR to reach USD 4,015.2 million by 2032. That figure comes from a market research vendor, so read it as a direction, not a forecast to bank on.
Global manufacturers should standardize device identity and data models across regions. A plant in Ohio and a plant in Pune should report in the same schema, or fleet-wide analytics stalls.
What to Look for in an IoT Solution Provider
Provider choice shapes data quality more than platform choice does. Ask for proof on six points.
-
Hardware and firmware skills, not only dashboard design.
-
Experience with industrial protocols such as OPC UA, MQTT, and Modbus.
-
Integration with your CRM, ERP, and maintenance systems.
-
Security controls, including device authentication and signed firmware updates.
-
A pilot plan with exit criteria you can measure.
-
References from projects in your industry, which you should call.
Be cautious when a proposal starts with the AI model. A credible partner asks about your assets, failure modes, and existing systems first.
Final Thoughts
Predictive maintenance succeeds or fails at the device layer. A model is only as good as the signals it receives, and those signals depend on sensor choice, connectivity, and clean asset mapping.
Start with your costliest assets. Capture the right signals, connect them to work orders, and measure the result in hours and dollars.