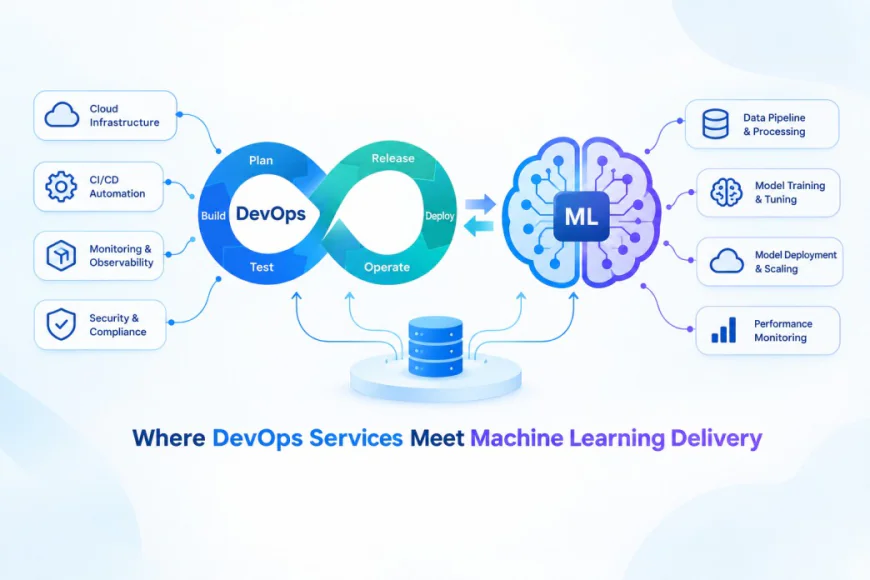
Where DevOps Services Meet Machine Learning Delivery
ML models stall between notebook and production. See where DevOps services meet machine learning delivery to ship models faster and with fewer surprises.
 jamessmithcorner
Our platform team ran mature DevOps Services internally. Our data science team shipped models by sending a file to an engineer. Both groups were competent. Neither understood why the other's process looked unreasonable.
Closing that gap took a year. Here is what transferred from one discipline to the other, and what did not.
Models are deployable artefacts, eventually
The first argument we had.
Data scientists experiment, and experimentation should not be constrained by release process. That is correct, and it stops being correct the moment something runs against real customers.
We drew the line explicitly. Experimentation is unconstrained. Anything serving a prediction in production goes through the same pipeline as any other deployable thing, with the same review, the same rollback, and the same on call expectation.
Most of the pipeline transfers unchanged
Less was special than either side expected.
Version control, automated build, artefact registry, staged environments, infrastructure as code, and monitoring all applied directly. Our DevOps Services practice had those and the model work simply adopted them.
The container discipline in particular transferred without modification. A model serving container is a container.
Three things genuinely differ
Worth naming, because they are where MLOps Services earn their separate name.
Models depend on data as well as code, so versioning covers three things rather than one. A model can degrade without any change to it, because the world moved. And testing cannot assert one correct answer, only that performance against a held out set has not worsened.
Everything else is ordinary delivery engineering.
Version data with the code
The practice that took longest to adopt.
Every model records the code, the training data snapshot, the feature definitions, and the hyperparameters. Any model in production can be rebuilt exactly.
Our data scientists found this bureaucratic for about two months and now rely on it. The first time somebody asked why a model behaved differently from the one tested in March, the answer took an hour instead of a week.
Gate on performance, not on passing
Normal tests pass or fail. Model checks compare.
Our pipeline refuses to promote a model that performs worse than the one in production on a fixed evaluation set, that behaves inconsistently across customer groups, or that is slower than the latency budget.
That has stopped four promotions. Two were genuine regressions and two were a test set problem, which was worth finding as well.
Monitor for silence, not errors
The failure mode that caught us.
A model that has quietly become inaccurate does not throw errors. It returns answers within normal latency, and only the quality has changed.
We watch input distributions against training, prediction patterns over time, and real outcomes where they arrive. Those checks found a degraded pricing model that had been wrong for weeks without a single alert from the ordinary monitoring.
Deploy the same way, roll back the same way
Shadow mode first, then a small share of traffic, then more.
The previous version stays deployable for thirty days. Rolling back is the same operation as rolling back a service, which means the on call engineer already knows how.
That consistency is the main argument for keeping model deployment inside the existing DevOps Services practice rather than building something parallel.
Keep the cost visible
Models are expensive in ways ordinary services are not.
Training runs, inference at scale, and the storage behind feature pipelines all accumulate quietly. Our first year of model serving cost more than the rest of the platform combined, and nobody had forecast it.
We now report cost per model alongside its performance, monthly. Two models were retired because the figures sat next to each other and the comparison was obvious.
DevOps Services already had cost reporting per service. Extending it to models took a fortnight and should have happened at the start.
Decide who carries the pager
The organisational question that mattered more than the tooling.
Ours is the team that owns the service, with data science available for anything requiring model judgement. The platform problems are platform problems and the engineer on call handles them.
Before we settled that, every model incident escalated to one data scientist, who became a single point of failure and eventually left.
What we standardised
● Experimentation unconstrained, production standardised.
● Code, data, features and parameters versioned together.
● Promotion gated on comparative performance, not a pass mark.
● Input, output and outcome monitoring with named owners.
● Shadow mode, staged rollout, thirty day rollback window.
● Service team on call, data science on standby for judgement.
Common questions
Do we need a separate platform?
Mostly not. MLOps Services added three capabilities to our existing pipeline rather than replacing it.
Is a separate team needed?
No. Model operations sit best inside the platform team, with data science involved in the model specific parts rather than running a parallel practice.
Who should own the pipeline?
Platform engineering, with data science involved in the model specific parts. A parallel pipeline owned separately diverges within a year.
What about generative features?
The same discipline, different checks. Generative AI for enterprises needs evaluation against written criteria rather than an accuracy figure, and the versioning, rollback and monitoring requirements are identical.
What is the most common gap?
Monitoring. Teams that deploy models well often have no way of knowing when one has quietly stopped being right.
Where we ended up
Models now ship weekly through the same pipeline as everything else, with the same rollback and the same people on call.
The data scientists kept their freedom to experiment and gave up the file transfer. Our DevOps Services practice gained three model specific capabilities and otherwise did what it already did. Most of the year was spent arguing about where the line sat, and almost none of it on building anything new.