When AWS Operations Become Too Complex to Manage Alone
When AWS Operations Become Too Complex to Manage Alone
 paulswalkers
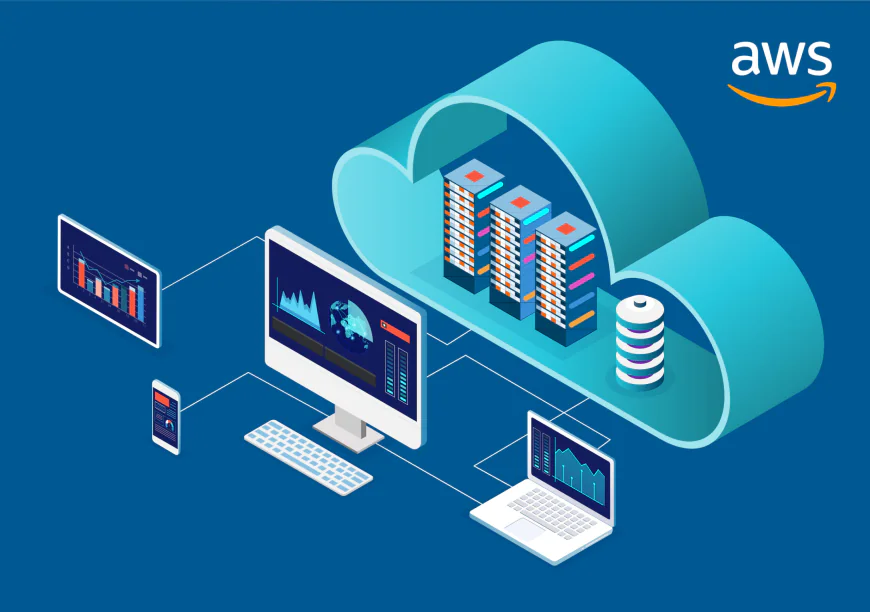
AWS makes it remarkably easy to launch infrastructure, scale applications, and add services as a business grows. The problem usually begins later. An EC2 environment expands, databases accumulate, Kubernetes clusters become harder to maintain, and monthly cloud costs start moving in directions nobody can immediately explain. At the same time, internal engineers are expected to manage alerts, security updates, backups, performance issues, and infrastructure changes while continuing to deliver new product features.
That is where an aws cloud managed service provider can change the operational equation. Instead of treating cloud management as another responsibility for an already busy engineering team, managed services provide dedicated operational ownership across monitoring, security, optimization, reliability, and ongoing administration.
Why AWS Environments Become Difficult to Manage
Cloud infrastructure rarely becomes complicated overnight. It usually happens through gradual growth.
A company may begin with a few EC2 instances and an RDS database. Then traffic increases, additional environments are introduced, containers are adopted, new IAM roles are created, and automated scaling is added. Before long, the original architecture has evolved into an environment involving multiple AWS services, accounts, workloads, and access policies.
The technical challenge is not simply knowing how each AWS service works. It is keeping the entire environment consistent and healthy over time.
An aws managed services provider can take responsibility for these ongoing operational requirements, helping businesses avoid the common situation where infrastructure management becomes reactive rather than planned.
Continuous Monitoring Instead of Reactive Troubleshooting
One of the biggest operational differences between self-managed infrastructure and managed AWS operations is how problems are handled.
Without continuous oversight, an issue may only become visible after customers experience slow application performance or an outage. A managed team can use tools such as Amazon CloudWatch, Grafana, and AWS-native monitoring capabilities to track infrastructure behavior continuously.
This includes watching CPU and memory utilization, database performance, storage consumption, application metrics, error rates, and other indicators of potential degradation.
The goal is not simply to generate more alerts. Effective monitoring means identifying meaningful signals and establishing response procedures around them. When a workload begins behaving differently from its normal pattern, the issue can be investigated before it develops into a larger business problem.
Keeping AWS Costs Under Control
Cloud spending can also become difficult to manage as environments grow.
An oversized EC2 instance might continue running for months. Storage volumes may remain attached after workloads have changed. Old snapshots can accumulate, while resources created for temporary projects may never be removed.
An experienced aws cloud managed service provider can introduce recurring cost reviews rather than waiting for an unexpectedly high invoice to trigger investigation.
Rightsizing recommendations, unused-resource identification, storage reviews, Savings Plans or Reserved Instance considerations, and AWS Cost Explorer analysis can all contribute to more disciplined cloud spending.
The important point is consistency. Cost optimization is rarely a single project that permanently solves cloud waste. Usage changes continuously, so optimization needs to change with it.
Security Requires Ongoing Attention
AWS provides extensive security capabilities, but configuring them correctly is only the beginning.
IAM permissions need periodic review as employees, applications, and services change. Security groups can become unnecessarily permissive. Systems require patching, and threat detection needs continuous monitoring.
Managed AWS operations can incorporate services such as AWS GuardDuty, AWS WAF, AWS Shield, and CloudTrail into broader security and governance processes. Regular access reviews and configuration checks can help identify weaknesses before they become operational problems.
This is particularly important for organizations handling sensitive information or operating under industry-specific compliance requirements. Security cannot realistically be treated as a one-time infrastructure hardening exercise when the underlying environment continues changing.
Database Management Is More Than Keeping RDS Running
Amazon RDS and Amazon Aurora simplify database administration, but managed database services still require attention.
Performance can change as applications grow. Queries may become more demanding, storage requirements can increase, and configuration settings may need adjustment. Backup strategies also need validation rather than simply being enabled and forgotten.
An AWS managed services team can monitor database health, review resource utilization, investigate performance anomalies, and help maintain appropriate backup and recovery procedures.
The same principle applies to high-availability architectures. A backup that has never been restored in a realistic test provides less confidence than a recovery process that has been exercised and documented.
Supporting Containers and Modern Applications
Modern applications often introduce another layer of operational complexity.
Organizations using Amazon EKS or Amazon ECS need to manage clusters, deployments, networking, scaling, security configurations, and the container infrastructure underneath their applications.
As environments expand, configuration drift can develop between clusters and deployment environments. Updates can also introduce compatibility or performance concerns.
Managed AWS cloud services can provide ongoing administration for these environments, including cluster monitoring, scaling reviews, configuration management, and infrastructure-as-code practices using tools such as Terraform or AWS CloudFormation.
This creates a more repeatable operating model and makes infrastructure changes easier to track and reproduce.
Giving Internal Engineers Their Time Back
Perhaps the most significant benefit of managed AWS operations is not a specific technical service.
It is reclaimed engineering capacity.
Every hour an application engineer spends investigating an infrastructure alert is an hour that cannot be spent improving the product. Every late-night escalation adds operational pressure that can eventually affect team productivity and morale.
An aws cloud managed service provider can absorb much of the routine operational workload, allowing internal teams to focus on application development, customer experience, architecture, and business priorities.
That does not mean internal engineers lose control of the environment. Instead, responsibilities become clearer. The managed team handles defined operational activities while internal stakeholders retain visibility through reporting, dashboards, escalation procedures, and agreed service expectations.
What Effective Managed AWS Operations Should Include
A meaningful managed service relationship should extend beyond basic ticket support.
Depending on the environment, businesses may require:
-
24/7 infrastructure monitoring
-
EC2 administration and rightsizing
-
RDS and Aurora performance management
-
IAM governance and access reviews
-
AWS WAF and security configuration management
-
GuardDuty and CloudTrail monitoring
-
EKS and ECS operational support
-
Backup and disaster-recovery validation
-
Cost optimization and usage analysis
-
Infrastructure-as-code management
-
Patch and configuration management
-
Regular operational and governance reporting
The exact combination should depend on the workload. A small internal application does not necessarily require the same operating model as a customer-facing SaaS platform processing transactions around the clock.
Measuring the Real Business Impact
The success of managed AWS services should ultimately be visible in business outcomes.
Are unnecessary cloud expenses being identified? Are incidents being detected and resolved more efficiently? Are backups actually recoverable? Are security reviews happening consistently? Is the internal engineering team spending less time on repetitive infrastructure administration?
These questions provide a more meaningful measurement framework than simply counting support tickets.
A well-structured aws cloud managed service provider relationship brings cost management, reliability, security, and operational accountability into the same process. Instead of treating each issue separately, it creates an ongoing system for keeping AWS infrastructure aligned with changing business requirements.
Conclusion: Moving From Cloud Ownership to Cloud Control
AWS gives organizations tremendous flexibility, but flexibility also creates responsibility. As environments grow, unmanaged operational complexity can quietly become expensive, risky, and distracting.
The answer is not necessarily to outsource every technical decision. It is to determine which responsibilities require continuous specialist attention and establish clear ownership for them. For many organizations, an AWS managed services model can provide that structure while allowing internal teams to concentrate on innovation rather than routine infrastructure maintenance.
The more important question may therefore be less about whether a business uses AWS and more about how deliberately it manages the environment after deployment. As cloud infrastructure becomes increasingly central to everyday operations, organizations that treat monitoring, security, cost governance, and reliability as continuous disciplines will be better positioned to turn cloud investment into sustainable operational value.