Vector Databases Explained: The Infrastructure Behind Modern AI Search
A practical explainer on vector databases, how embeddings work, why traditional databases can’t do semantic search, and where this infrastructure shows up in AI products.
 mobcoder ai
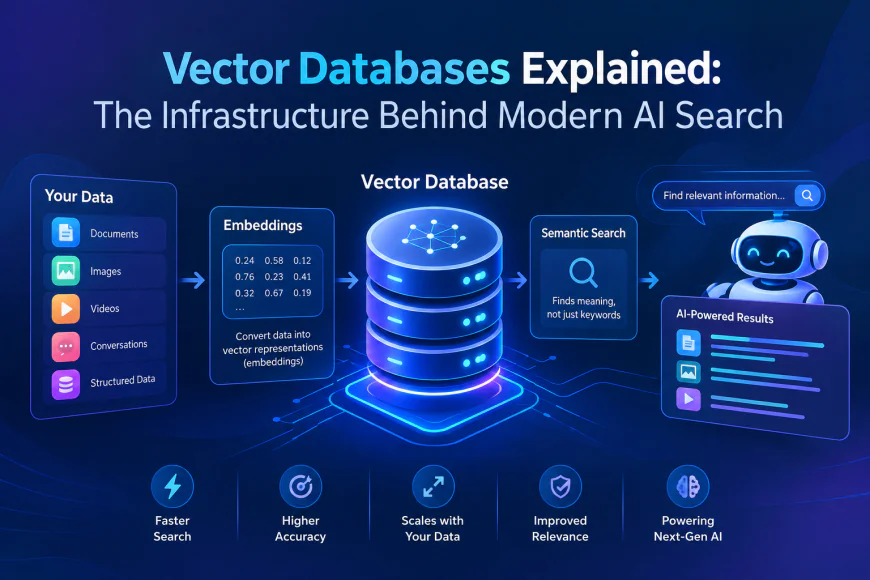
Type “red running shoes” into a search bar built on a traditional database and it looks for exact matches to those words. Upload a photo of a pair of red running shoes and ask a modern AI-powered app to find similar ones, and something entirely different happens under the hood. There are no words to match. Instead, the system converts the image into a long list of numbers, a vector, and searches for other vectors that sit close to it in mathematical space. That’s the basic idea behind a vector database, and it’s the quiet piece of infrastructure sitting underneath most of what people now call “AI search.”
It’s also the infrastructure that made modern Image Search Techniques possible in the first place. Older systems needed a human to type descriptive tags onto every image, because there was no way to search by visual similarity directly. Vector databases removed that requirement by giving every piece of content, image, text, or audio, a numerical fingerprint that captures meaning, and then making it possible to search for “things like this” at scale, in milliseconds, across millions of records.
What a Vector Actually Is
A vector, in this context, is a list of numbers, typically somewhere between a few hundred and a few thousand values, produced by an embedding model. That model has been trained to convert an input, a sentence, an image, a product description, into a point in a high-dimensional space, positioned so that similar inputs land close together and dissimilar ones land far apart.
The specific numbers in a vector don’t mean anything on their own; a human looking at the raw values would learn nothing. What matters is the relationships between vectors. Two product photos of similar sneakers will have vectors that are close together, even if the images use different lighting, angles, or backgrounds, because the embedding model learned to focus on the features that actually define “sneaker-ness” rather than surface-level pixel differences.
Why Traditional Databases Can’t Do This
A standard relational database is built for exact matches and structured queries: find every row where the price is under fifty dollars, or where the category equals “footwear.” It has no concept of “similar” the way a person means it. Ask it to find products similar to a given item and it has nothing to compare beyond whatever exact fields were manually tagged.
A vector database is purpose-built for a different question entirely: given this point in space, what are the nearest other points? That’s a fundamentally different kind of search, called approximate nearest neighbor search, and it requires specialized indexing structures, things like HNSW graphs or IVF indexes, that traditional databases were never designed to support efficiently at scale.
How a Vector Database Fits Into a Real System
In practice, vector databases rarely operate alone. A typical pipeline looks like this: content comes in, whether that’s a product catalog, a set of support documents, or a library of images, and gets passed through an embedding model to generate a vector for each item. Those vectors get stored in the vector database alongside a reference back to the original content. When a user submits a query, that query also gets embedded using the same model, and the database returns the closest matching vectors, which map back to the original items.
This pattern shows up under a few different names depending on the application. In e-commerce, it’s visual or semantic product search. In enterprise software, it’s the retrieval half of a retrieval-augmented generation pipeline, pulling relevant documents for a language model to reason over. In recommendation systems, it’s the engine behind “customers who liked this also liked.”
Where Vector Databases Show Up in Production
Semantic and visual search. Users search by meaning or by image instead of exact keywords, finding relevant results even when the words they used don’t match the words in the underlying content.
Recommendation engines. Products, articles, or media get recommended based on vector similarity to what a user has already engaged with, rather than rigid rule-based categories.
Fraud and anomaly detection. Unusual transactions or behavior patterns show up as vectors that sit far from the normal cluster, making outliers easier to flag automatically.
AI agent memory. Agents that need to recall relevant past interactions or documents rely on vector search to pull the right context into a conversation without scanning every record manually.
Choosing a Vector Database: What Actually Matters
The vector database landscape has grown crowded fast, with options ranging from dedicated products to vector extensions bolted onto existing databases. A few practical factors tend to matter more than marketing claims.
Scale and latency requirements. A catalog with ten thousand items has very different performance needs than one with a hundred million, and some databases handle that jump far more gracefully than others.
Filtering alongside similarity search. Real queries are rarely pure similarity searches. A shopper wants items similar to this photo, under fifty dollars, in stock. Not every vector database handles combined filtering and similarity search efficiently, and this is a common place performance quietly falls apart in production.
Update frequency. Some databases handle frequent inserts and updates smoothly; others are optimized for mostly-static datasets and slow down noticeably under constant change, which matters a great deal for catalogs or knowledge bases that update daily.
Operational overhead. Self-hosting gives more control but adds real infrastructure work. Managed options reduce that burden at a recurring cost, and the right tradeoff depends heavily on team size and existing infrastructure expertise.
A Simple Way to Picture It
It helps to picture a vector database as a library where books aren’t shelved alphabetically by title, but physically positioned based on what they’re about. A book on Italian cooking sits near other cookbooks, but also drifts closer to travel guides about Italy than it does to a cookbook about Japanese cuisine, because the underlying meaning connects it to both neighborhoods at once. Searching that library means walking to the right neighborhood and looking at what’s nearby, rather than scanning a title index for exact keyword matches. That’s essentially what a vector database does at massive scale, thousands of times a second, across data types a human librarian could never organize by hand.
Frequently Asked Questions
What is a vector database used for?
It stores content as numerical representations called embeddings and allows searching by similarity rather than exact keyword matches, which powers semantic search, visual search, recommendations, and AI systems that need to retrieve relevant context.
How is a vector database different from a regular database?
A regular database is optimized for exact matches on structured fields. A vector database is optimized for finding the nearest neighbors to a given point in a high-dimensional space, enabling similarity-based rather than exact-match search.
Do I need a vector database for basic AI search?
For anything beyond simple keyword matching, semantic search, image similarity, or recommendations, yes. Vector search is generally what makes those features work at meaningful accuracy and scale.
Can vector databases handle both images and text? Yes, as long as an embedding model has converted the content into vectors first. The database itself is agnostic to the original data type; it only works with the resulting numerical vectors.
Choosing and implementing the right vector infrastructure is one of those decisions that’s easy to underestimate early and expensive to redo later. It’s a piece of the puzzle Mobcoder AI works through regularly as part of its broader AI development services, alongside related infrastructure work like the monitoring layer described in Server Intelligence Agent, helping teams build search and retrieval systems that hold up as data volume grows.