Synthetic Data Engine Architectures for Enterprise Model Training
Explore how synthetic data engines, generative adversarial pipelines, and privacy-compliant simulation environments overcome data scarcity in enterprise AI.
 mobcoder ai
Developing high-accuracy machine learning models requires massive volumes of diverse, high-quality training data. However, real-world data collection is frequently constrained by strict privacy regulations, high annotation costs, rare edge-case occurrences, and inherent historical data biases. In industries like healthcare, finance, and autonomous driving, acquiring sufficient labeled training samples can take months or years, stalling software development timelines.
Synthetic data engine architectures offer a scalable solution to data scarcity. By leveraging generative models, physics-based simulations, and statistical sampling algorithms, enterprises generate high-fidelity, privacy-compliant training datasets on demand. When organizations build custom synthetic generation pipelines, collaborating with an expert AI Development Company in Vancouver allows engineering teams to construct mathematically validated data generation pipelines that accelerate model training without compromising data privacy standards.
The Architectural Blueprint of Synthetic Data Engines
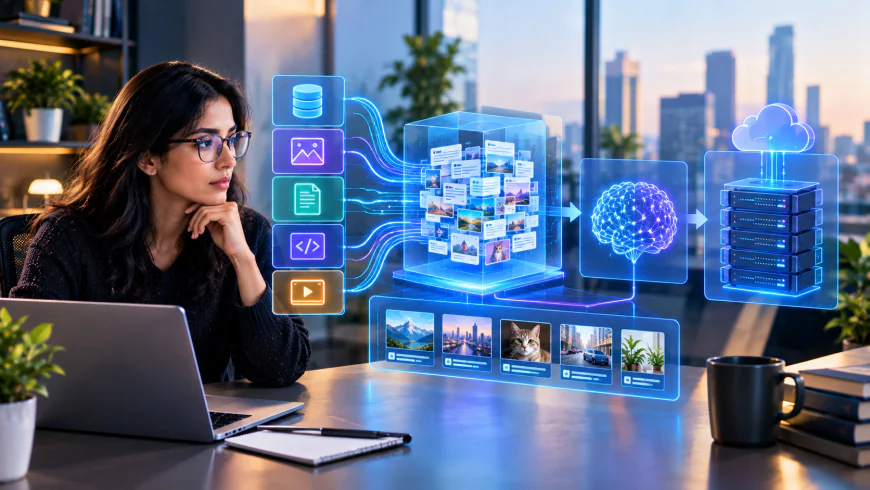
A modern enterprise synthetic data engine is not a simple random number generator or basic text paraphrasing script. It is an end-to-end data processing infrastructure that maintains the exact statistical distributions, feature correlations, and domain constraints of real-world datasets.
Core components of a scalable synthetic data engine include:
-
Generative Modeling Core: Utilizing Generative Adversarial Networks (GANs), Variational Autoencoders (VAEs), and Diffusion Models to model multi-dimensional feature distributions.
-
Physics and Simulation Runtime: Executing 3D physics engines like NVIDIA Omniverse to simulate photorealistic lighting, material properties, and sensor noise for visual data generation.
-
Differential Privacy Filters: Injecting mathematical noise during generation to ensure individual synthetic samples cannot be reverse-engineered to reveal private real-world data points.
By combining generative models with simulation environments, synthetic data engines produce perfectly annotated data at scale, complete with automated bounding boxes, semantic segmentation masks, and precise ground-truth metadata tags.
Overcoming Privacy Barriers in Regulated Verticals
Data protection standards like GDPR, HIPAA, and regional privacy acts restrict how personal identifiable information can be used for software development. Training public-facing models on raw financial records or patient medical histories creates severe compliance liabilities.
Synthetic data engines resolve this tension by generating anonymized, mathematically equivalent proxy datasets. Generative models learn the underlying statistical relationships, risk correlations, and behavioral patterns of patient populations without copying actual individual identity records.
When building conversational systems or handling customer communications, implementing advanced Agentic AI Development Services allows enterprises to integrate synthetic dialogue generators. This ensures customer service models are trained on rich, natural interaction scenarios while keeping proprietary customer logs fully protected.
Improving Edge Case Training Through Targeted Generation
In many industrial applications, the most critical data samples are the rarest. For instance, an autonomous vehicle may drive millions of miles without encountering a dangerous multi-vehicle collision during a severe snowstorm. If a machine learning model is trained exclusively on routine driving footage, it will fail when encountering rare edge cases in production.
Synthetic data engines allow developers to artificially amplify rare occurrences:
-
Parameterized Scenario Manipulation: Dynamically adjusting environmental variables, such as changing weather conditions, lighting angles, and obstacle positions in 3D simulation spaces.
-
Feature Distribution Balancing: Oversampling underrepresented demographic groups or rare fraud categories to eliminate algorithmic bias before model deployment.
-
Adversarial Edge Case Synthesis: Using generative algorithms to generate complex visual or tabular anomalies specifically designed to stress-test model decision boundaries.
Targeted synthetic amplification ensures that models learn to handle unexpected real-world conditions robustly, reducing operational failure rates in high-stakes environments.
Evaluating Synthetic Data Quality and Fidelity
Generating synthetic data at volume is useless if generated samples introduce statistical distortions or mode collapse into model training loops. Synthetic data engines require continuous validation using rigorous mathematical metrics.
Evaluation teams track three key quality dimensions:
Fidelity Metrics: Measuring how closely synthetic feature distributions match real-world reference datasets using statistical distance tests like Wasserstein Distance and Jensen-Shannon Divergence.
Utility Metrics: Assessing model performance when trained on synthetic data versus real-world data. High utility means a model trained entirely on synthetic samples achieves equivalent accuracy on real test sets.
Privacy Risk Metrics: Calculating nearest-neighbor distance to real training samples to guarantee the generator is not memorizing and reproducing sensitive source records.
Businesses scaling autonomous task automation can pair synthetic data generation with specialized AI Agent Development Services, ensuring autonomous agents are rigorously tested across thousands of simulated operational environments before live deployment.
Conclusion and Future Outlook
Synthetic data engines are fundamentally changing how enterprises approach machine learning development. By decoupling model training from the slow, expensive process of real-world data collection, organizations drastically reduce software development timelines while eliminating data privacy risks. As generative techniques continue to improve, synthetic data will become the primary foundation for training robust, resilient, and unbiased artificial intelligence applications across global industries.