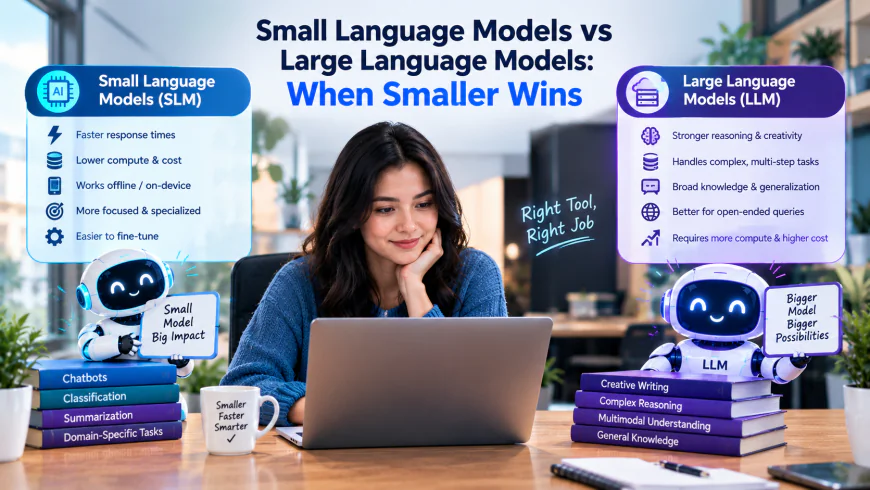
Small Language Models vs Large Language Models: When Smaller Wins
A practical comparison of small and large language models, where each one actually wins in production, and how businesses are deciding which to deploy in 2026.
 mobcoder ai
For a couple of years, the industry conversation about AI models followed one direction: bigger is better. More parameters, more training data, more compute, better results. That trend hasn’t reversed exactly, but it’s been joined by a quieter, equally important counter-trend, small language models that are deliberately compact, cheaper to run, and in a growing number of production use cases, genuinely better suited to the job than their massive counterparts.
This shift shows up constantly in how businesses actually build now. An AI Development Company in Seattle recently helped a client replace a general-purpose large model handling internal document classification with a small model fine-tuned specifically on that company’s document types, cutting inference cost by more than 80 percent while modestly improving accuracy on the narrow task. That’s not an unusual outcome. It’s becoming the expected one for well-scoped, repetitive tasks.
What Actually Separates a Small Model From a Large One
There’s no strict industry-wide cutoff, but small language models generally refer to models in the range of a few hundred million to a few billion parameters, versus large models that run into the tens or hundreds of billions. The parameter count roughly correlates with how much the model can “remember” from training and how nuanced its reasoning can be across a wide range of topics.
The more useful way to think about the distinction isn’t raw size, though, it’s specialization versus generality. A large model is trained to be broadly competent across an enormous range of tasks, writing, coding, reasoning, translation, general knowledge. A small model, especially a fine-tuned one, is often trained or adapted to do one category of task very well, at the cost of being much worse at everything outside that scope.
Where Large Models Still Clearly Win
Open-ended reasoning across unfamiliar topics remains a large model’s strength. If a task requires broad world knowledge, creative problem solving, or handling genuinely novel requests the system has never seen a close analog of during training, a large model’s breadth matters.
Complex, multi-step tasks that require holding a lot of context and reasoning across it, like analyzing a lengthy legal document for inconsistencies, tend to favor larger models, because the reasoning quality gap widens as task complexity increases.
Conversational flexibility, handling an unpredictable range of user questions in an open-ended chat interface, still generally favors large models, since a small model’s narrower training makes it more likely to stumble on requests outside its specialty.
Where Small Models Genuinely Win
Cost and latency at scale. A small model can be an order of magnitude cheaper to run per request and meaningfully faster, which matters enormously for any application processing high volumes of requests where a two-second delay per query adds up fast across millions of calls.
Well-defined, repetitive tasks. Classification, extraction, sentiment tagging, and other narrow tasks with a clear, learnable pattern are exactly where fine-tuned small models excel, often matching or beating a general-purpose large model on the specific task while costing a fraction as much.
On-device and edge deployment. Small models fit on hardware large models simply can’t run on, phones, embedded devices, on-premise servers with limited compute, making them the only realistic option when data can’t leave the device or a network round trip isn’t acceptable.
Data privacy and control. Running a smaller model on infrastructure a company fully controls avoids sending sensitive data to a third-party API at all, which matters a great deal in regulated industries handling healthcare or financial information.
The Fine-Tuning Advantage Small Models Have
One underappreciated reason small models perform well on narrow tasks is that they’re far cheaper and faster to fine-tune. Adjusting a small model’s weights on a company’s specific data, its actual document formats, its actual customer language, its actual product catalog, takes a fraction of the compute a large model fine-tune requires, and can often be done with a much smaller labeled dataset. That means a business can iterate on a small model several times as it learns what actually works, while a large model fine-tune is a slower, more expensive commitment to get right the first time.
This dynamic is part of why infrastructure monitoring and operational tooling has leaned toward smaller, purpose-built models for specific detection tasks. A system like Server Intelligence Agent, for example, benefits from fast, cheap, narrowly-scoped models running constantly against telemetry data, reserving a larger reasoning model only for the moments something genuinely anomalous needs deeper investigation.
How Teams Are Actually Deciding
The practical pattern that’s emerged in production systems is rarely “pick one.” It’s routing: use a small, fast, cheap model as the default for the bulk of requests, and escalate to a large model only when the task is genuinely complex enough to need it. This tiered approach captures most of the cost savings of small models while keeping large-model capability available for the harder cases that actually require it.
Getting that routing logic right is its own design problem. Send too much to the small model and quality suffers in cases it can’t handle well. Send too much to the large model and the cost savings never materialize. The teams getting real value out of this approach tend to invest specifically in measuring, by task category, which tier is actually needed, rather than guessing.
A Simple Mental Model
Think of it less as “which model is better” and more as choosing the right tool for a specific job’s actual shape. A large model is a generalist consultant who can reason about almost anything you bring to them, at a cost that reflects that breadth. A small, fine-tuned model is a specialist who’s seen thousands of examples of one specific kind of problem and handles it quickly and cheaply, but would be genuinely out of their depth on something outside that narrow lane. Neither framing knocks the smaller model. A specialist who’s excellent at one recurring task is often exactly what a production system needs, and paying consultant rates for that same narrow task is usually just wasted budget.
Frequently Asked Questions
Are small language models less accurate than large ones?
On broad, general tasks, generally yes. On narrow, well-defined tasks they’ve been fine-tuned for specifically, small models frequently match or exceed large general-purpose models, since specialization often outperforms raw scale for a focused task.
Why would a business choose a small model over a more capable large one?
Cost, speed, and the ability to run on limited hardware are the main drivers. A small model that’s good enough for a specific task and dramatically cheaper to run at scale is often the better business decision, even if a large model would technically perform slightly better.
Can small and large models be used together in the same system?
Yes, and this is increasingly the standard architecture. Many production systems route the bulk of requests to a small, fast model and escalate only the genuinely complex cases to a larger model, balancing cost against capability.
Do small models require less data to fine-tune?
Generally yes, both in terms of the amount of labeled data needed and the compute required to run the fine-tuning process itself, which makes them significantly more practical for companies without large, established data pipelines.
Figuring out whether a task genuinely needs a large general-purpose model or would perform just as well, and far more cheaply, on a fine-tuned small model is a decision worth making deliberately rather than defaulting to whichever model is trending. That kind of model selection and cost analysis is part of what Mobcoder AI works through under its broader AI development services, matching the model to the actual task instead of the other way around.