RTX PRO 6000 for AI Inference: Models, Performance, and Cloud Deployment
Explore how the NVIDIA RTX PRO 6000 powers AI inference, runs large language models, and supports cloud deployment. Learn about performance, VRAM, and costs.
 Prateek
AI is becoming part of everyday business operations. From customer support chatbots to AI-powered search, document summarization, and image generation, more applications now rely on AI models to deliver results in real time.
Behind these applications is AI inference, the process of using a trained model to generate responses or predictions. As models become larger and applications serve more users, choosing the right GPU becomes increasingly important.
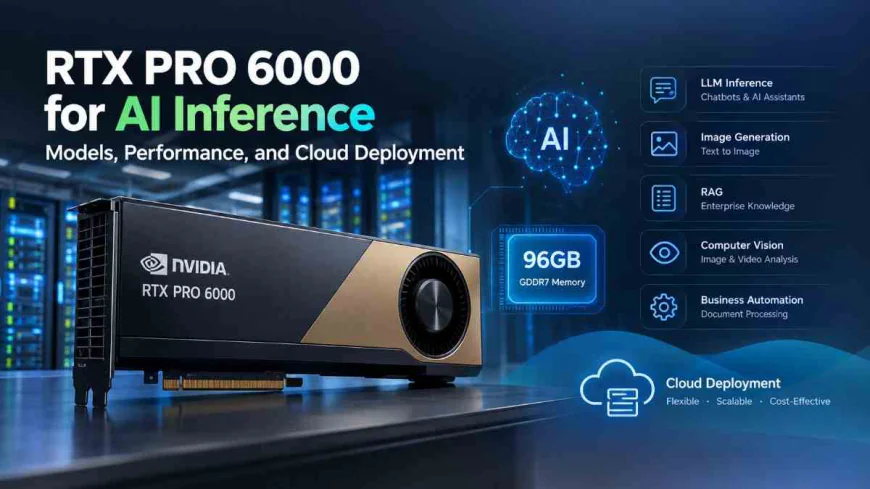
The NVIDIA RTX PRO 6000 Blackwell is one option worth considering. With 96GB of GDDR7 memory and a modern GPU architecture designed for demanding computing workloads, it can handle many AI inference tasks, including running large language models.
But what makes this GPU suitable for inference, which models can it run, and when does renting one make more sense than buying it? Let's take a closer look.
What Is AI Inference?
AI inference happens whenever a trained AI model processes new information and produces an output.
For example, when someone asks a question in an AI chatbot, the model processes the prompt and generates a response. The same process powers image recognition tools, AI writing assistants, recommendation systems, and many other applications.
Some common AI inference workloads include:
-
Large language models (LLMs): Powering chatbots, AI assistants, and text-generation tools.
-
Retrieval-augmented generation (RAG): Helping AI applications answer questions using company documents and internal knowledge bases.
-
Image generation: Creating images from written prompts.
-
Computer vision: Identifying objects, analyzing images, and processing video.
-
Business automation: Summarizing documents, extracting information, and handling repetitive tasks.
The GPU you choose can affect how quickly these applications respond, how many users they can serve, and how large a model you can run.
Why Use RTX PRO 6000 for AI Inference?
Not every AI application needs a high-end GPU. However, workloads involving larger models, longer conversations, or multiple simultaneous users can benefit from additional GPU memory and computing power.
The RTX PRO 6000 Blackwell brings several features that make it worth considering for these workloads.
1. 96GB of Memory for Larger AI Models
GPU memory, also known as VRAM, is one of the first things to consider when selecting hardware for AI inference.
A model needs memory to store its weights, but that is only part of the requirement. The inference software, temporary data, and conversation context also consume VRAM.
The RTX PRO 6000 Blackwell comes with 96GB of GDDR7 memory and error-correcting code (ECC). This gives developers room to run many quantized large language models on a single GPU, depending on the model and deployment settings.
Consider a 70-billion-parameter model. At approximately 8-bit precision, its weights alone may require around 70GB of memory. The inference engine and KV cache need additional space, so the complete workload must be evaluated before deployment.
This is where a GPU with 96GB of memory can be useful, particularly for teams that want to run larger models without immediately moving to a multi-GPU setup.
2. Blackwell Architecture for Modern AI Workloads
The RTX PRO 6000 uses NVIDIA's Blackwell architecture and features fifth-generation Tensor Cores.
These capabilities support modern AI computing techniques, including lower-precision formats such as FP4. When a model and its inference software support these formats, developers may be able to reduce memory requirements and improve inference efficiency.
The actual improvement depends on the model, quantization method, software framework, and workload. It is always a good idea to test your application rather than relying entirely on theoretical performance figures.
3. Suitable for More Than One Type of AI Application
AI workloads vary considerably. A team might use a GPU to develop a chatbot today and later use the same infrastructure for document processing, image generation, or other machine learning tasks.
The RTX PRO 6000 can be considered for a range of professional AI workloads, including LLM inference, generative AI, and computer vision.
For production applications, however, the right configuration also depends on request volume, response-time requirements, software compatibility, and how consistently the GPU will be used.
Which AI Models Can Run on RTX PRO 6000?
The models you can run depend on their size, numerical precision, context length, and the amount of memory required by the inference engine.
The table below provides a rough estimate of model-weight memory requirements.
|
Model size |
Memory at 16-bit precision |
Memory at 8-bit precision |
|
7B parameters |
14GB |
7GB |
|
13B parameters |
26GB |
13GB |
|
30B parameters |
60GB |
30GB |
|
40B parameters |
80GB |
40GB |
|
70B parameters |
140GB |
70GB |
These are estimates for model weights alone. Actual memory usage will be higher because the GPU also needs space for the inference engine, KV cache, and other runtime operations.
Running Smaller Models: 7B and 13B
Smaller language models are often used for chatbots, text summarization, internal search, classification, and basic AI assistants.
The RTX PRO 6000 has enough memory to provide additional flexibility with these workloads. Depending on the application, that could mean supporting longer prompts, handling more concurrent requests, or experimenting with different model configurations.
However, the GPU you need will depend on the expected workload. If your application only uses a small model with limited traffic, a less expensive GPU may be sufficient.
Running Mid-Sized Models: 30B to 40B
Mid-sized models can be useful when an application needs more capable text generation or reasoning, although performance varies from model to model.
At 8-bit precision, many models in this range can fit comfortably within 96GB of VRAM. At 16-bit precision, memory requirements increase significantly. For example, a 40B model needs approximately 80GB for its weights alone, leaving less room for context and other runtime requirements.
Quantization can help reduce memory consumption, making these models easier to deploy on a single GPU.
Running Large Models: 70B
Running a 70B model is possible on a single RTX PRO 6000 in many quantized configurations, provided the complete workload fits within the available memory.
At 8-bit precision, the weights alone require approximately 70GB. This leaves some memory for the inference engine and KV cache, but the available space may become a limitation with long contexts or multiple concurrent users.
At 16-bit precision, the weights require approximately 140GB, which exceeds the memory capacity of a single RTX PRO 6000.
If your application requires full 16-bit weights, longer context windows, or high concurrency, you may need a larger-memory or multi-GPU configuration.
What Affects AI Inference Performance?
Having enough VRAM is important, but it does not automatically guarantee fast inference.
Several other factors influence how well a model performs in a real application.
Model Quantization
Quantization reduces the precision used to represent model weights. It can make larger models easier to fit into GPU memory and may improve inference speed.
The trade-off is that some quantization methods can affect model quality. The impact depends on the model and technique, so it is worth testing different configurations before deploying one in production.
Context Length
Longer prompts and conversations require additional memory to maintain the information needed to generate responses.
For example, an AI assistant that answers short questions may use considerably less memory than one that analyzes lengthy reports or maintains long conversations.
If your application relies on large context windows, account for KV cache requirements when selecting a GPU.
Number of Simultaneous Users
A model serving one user has different requirements from one handling dozens or hundreds of requests at the same time.
Higher concurrency can improve overall throughput when requests are efficiently batched, but it can also increase memory usage and affect response latency.
Before choosing a GPU, test your application with realistic traffic and measure metrics such as time to first token, tokens generated per second, and total request latency.
The Rest of Your Infrastructure
The GPU is only one part of an AI inference system.
CPU performance, system RAM, storage, networking, and the inference framework can all affect results. A well-balanced configuration helps prevent other components from becoming bottlenecks.
RTX PRO 6000 vs. Other GPUs for AI Inference
The RTX PRO 6000 is not necessarily the right choice for every AI workload. It helps to compare it with alternatives based on your model size and performance requirements.
|
Use case |
GPU to consider |
|
Smaller AI models and lightweight inference |
NVIDIA L4 |
|
Larger quantized LLMs on a single GPU |
NVIDIA RTX PRO 6000 Blackwell |
|
AI inference combined with professional graphics workloads |
NVIDIA RTX PRO 6000 Blackwell |
|
Large models requiring high memory bandwidth or multi-GPU scaling |
NVIDIA H100 or H200 |
The NVIDIA L4 may be sufficient for applications that prioritize efficient inference with smaller models. The RTX PRO 6000 is worth considering when additional memory capacity is important, while H100 and H200 configurations may be better suited to workloads that need higher memory bandwidth or multiple GPUs.
The best option depends on the model you intend to run, the number of requests you expect, and your budget.
Whenever possible, benchmark the same model on the configurations you are considering. Real-world results will provide a more useful comparison than specifications alone.
Should You Buy or Rent RTX PRO 6000 for AI Inference?
Once you have identified the right GPU, the next decision is how to access it.
Buying hardware gives you direct control over the system, while renting a cloud GPU can make it easier to start without a large upfront investment.
When Buying Makes Sense
Buying an RTX PRO 6000 may be a good option if your workload runs consistently and you expect to use the GPU for an extended period.
It may be particularly suitable for businesses that already have the necessary infrastructure and technical team to manage their own hardware.
Before purchasing, consider the cost of the GPU, the rest of the server, electricity, cooling, maintenance, and future upgrades. These expenses contribute to the total cost of ownership.
When Renting a Cloud GPU Makes Sense
Cloud GPU rental can be useful when you are developing an AI application, testing a new model, or working with workloads that change over time.
Instead of purchasing hardware upfront, you can access a suitable configuration based on your requirements and the provider's available plans.
Cloud GPU rental can be particularly useful when you want to:
-
Test an AI model before committing to dedicated hardware.
-
Launch a new application without investing in a physical GPU.
-
Scale your resources as demand changes.
-
Avoid managing physical hardware and its maintenance.
-
Compare different GPU configurations before making a long-term decision.
The actual savings depend on usage, rental rates, storage, networking, and other charges. For workloads that run continuously, purchasing hardware may be more economical over time.
If you are comparing the costs of both options, our guide to RTX PRO 6000 price in India explains the pricing considerations involved in buying or renting this GPU.
Deploy RTX PRO 6000 for AI Inference on CloudPe
If you want to run AI workloads without purchasing a physical GPU, cloud infrastructure is another option to consider.
CloudPe offers an RTX PRO 6000 Blackwell GPU for workloads such as AI inference, model development, and other supported GPU computing tasks.
Before choosing a configuration, consider the model you plan to deploy, its memory requirements, expected request volume, and the software frameworks you intend to use.
It is also worth checking the available GPU configuration, current pricing, storage options, and deployment details to make sure they match your requirements.
If you are still evaluating whether this GPU fits your budget, start with our guide to RTX PRO 6000 pricing in India. You can then compare the available options based on your workload and expected usage.