Retrieval-Augmented Generation: How AI Grounds Its Answers in Real Data
A clear breakdown of retrieval-augmented generation, how it works, why it exists, and where businesses are using it to make AI answers more accurate and trustworthy.
 mobcoder ai
Ask a language model a question about something that happened last week, or something buried in your company’s internal wiki, and it will often answer with total confidence and be completely wrong. Not because the model is broken, but because it’s doing exactly what it was trained to do: predict a plausible next word based on patterns it learned during training, not look anything up. The industry-standard fix is retrieval-augmented generation, usually shortened to RAG, and it works on a principle older than AI itself: don’t guess when you can check.
The underlying retrieval mechanics in RAG aren’t new. They’re a close cousin of the same vector-matching logic that reshaped Image Search Techniques over the past several years, converting content into numerical representations and finding the closest matches by meaning rather than exact keywords. RAG applies that same idea to text, letting a model pull in relevant documents before it writes an answer, instead of relying purely on what it memorized during training.
Why Plain Language Models Hallucinate
A language model’s knowledge is frozen at the point its training data was collected, and even within that window, it doesn’t store facts the way a database does. It stores statistical patterns across billions of examples, which is why it can write fluently about a topic it has no reliable information on. Ask it something outside its training data, and it will still generate a confident, grammatically correct answer, because generating confident, grammatically correct text is what it was optimized to do. Whether that answer is true is a separate question the model has no built-in way to check.
This is the core problem RAG was built to solve. Instead of asking the model to answer purely from memory, the system first retrieves relevant, verified information and hands it to the model as context, then asks the model to answer using that material specifically.
How a RAG Pipeline Actually Works
Strip away the branding and most production RAG systems follow the same basic sequence.
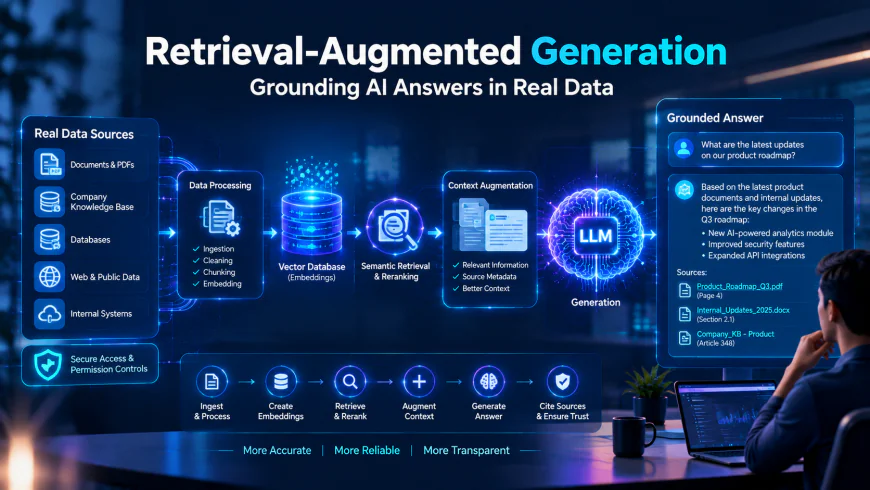
Indexing. Documents, whether that’s a knowledge base, a set of PDFs, or product documentation, get broken into chunks and converted into vector embeddings, then stored in a vector database for fast similarity search.
Query embedding. When a user asks a question, that question also gets converted into a vector using the same embedding model, so it lives in the same mathematical space as the indexed documents.
Retrieval. The system searches for chunks whose vectors are closest to the query’s vector, pulling back the handful of passages most likely to be relevant, typically somewhere between three and twenty depending on the setup.
Augmentation. Those retrieved passages get inserted into the prompt alongside the user’s original question, giving the model real source material to work from instead of relying on memory.
Generation. The model writes its answer grounded in the retrieved context, ideally with citations back to the source documents so a human can verify the claim.
The quality of the final answer depends heavily on the retrieval step. A model can only be as accurate as the material it’s given, so a weak retrieval system, one that pulls back irrelevant or outdated chunks, produces confidently wrong answers just as easily as a model with no retrieval at all.
Where RAG Shows Up in Practice
Internal knowledge search. Employees ask a chatbot a question and get an answer pulled from the company’s actual policy documents, not a generic response, with a link back to the source page.
Customer support. Support bots retrieve from product manuals and past resolved tickets, which noticeably cuts down on the kind of confident-but-wrong answers that erode trust in AI-powered support fast.
Regulated industries. Legal, healthcare, and financial teams use RAG specifically because it creates an audit trail. When an answer is grounded in a retrieved document, someone can trace exactly where it came from, which matters a great deal when the underlying content needs to be defensible.
Developer tools. Coding assistants retrieve from a company’s actual codebase and internal documentation rather than generic public training data, producing suggestions that match a team’s real conventions.
Where RAG Systems Commonly Go Wrong
RAG is not a guarantee of accuracy, and teams that treat it as a plug-and-play fix tend to run into the same handful of problems.
Chunking strategy matters more than most people expect going in. Split documents into pieces that are too small and you lose context; too large and you dilute relevance and waste room in the prompt. There’s no universal right answer, it depends on the structure of the source material.
Stale indexes are a quiet failure mode. If the underlying documents change and the vector index isn’t refreshed, the system will confidently retrieve outdated information and present it as current, which is arguably worse than a model admitting it doesn’t know.
Retrieval doesn’t always mean relevance. Vector similarity finds passages that are semantically close to the query, but “close” and “correct” aren’t the same thing, especially with ambiguous questions or documents that use similar language to describe different things.
Getting RAG Right in Production
Teams that get durable value out of RAG tend to invest early in a few specific areas: a chunking strategy that respects the actual structure of their documents, a retrieval evaluation process that checks whether the right passages are coming back, not just some passages, and a re-indexing pipeline that keeps the vector store current as source documents change. None of that is exotic engineering, but it’s the difference between a RAG system that earns trust over months and one that gets quietly abandoned after a few embarrassing answers.
RAG Versus Just Using a Bigger Context Window
A common question once a team understands RAG is why not just paste the entire knowledge base into the prompt and skip retrieval altogether, especially as models support longer context windows. In practice, this rarely holds up at scale. Larger context windows cost more per request, and research has repeatedly shown that models pay uneven attention across a long context, often weighting information at the beginning and end more heavily than material buried in the middle. Retrieval solves both problems by handing the model a small, carefully selected set of the most relevant passages instead of everything at once, which tends to produce more focused, more accurate answers, and costs a fraction as much per query.
Frequently Asked Questions
What does RAG stand for in AI?
Retrieval-augmented generation. It’s a technique where an AI model retrieves relevant documents before generating a response, grounding its answer in real source material instead of relying purely on memorized training data.
How is RAG different from fine-tuning a model?
Fine-tuning changes the model’s internal weights using new training examples, which is slow and expensive to update. RAG keeps the model unchanged and instead feeds it fresh, relevant information at the moment of the query, which is far easier to keep current.
Does RAG eliminate AI hallucinations?
No. It significantly reduces them by grounding answers in retrieved content, but a model can still misread or misapply what it retrieved, which is why source citations and human review remain important in high-stakes use cases.
What kind of database does RAG use?
Most RAG systems rely on a vector database, which stores content as numerical embeddings and retrieves results based on semantic similarity rather than exact keyword matches.
For teams evaluating whether their internal search, support, or documentation workflows are a fit for retrieval-augmented generation, the scoping work usually matters more than the model choice. That’s the kind of build Mobcoder AI works through as part of its Agentic AI development services, helping teams design retrieval pipelines that actually hold up once real users start asking real questions.