Why Retrieval-Augmented Generation Quietly Became Enterprise AI’s Backbone
Retrieval-augmented generation has become the default architecture for enterprise AI. Here’s why it works, where it breaks, and how to get it right.
 mobcoder ai
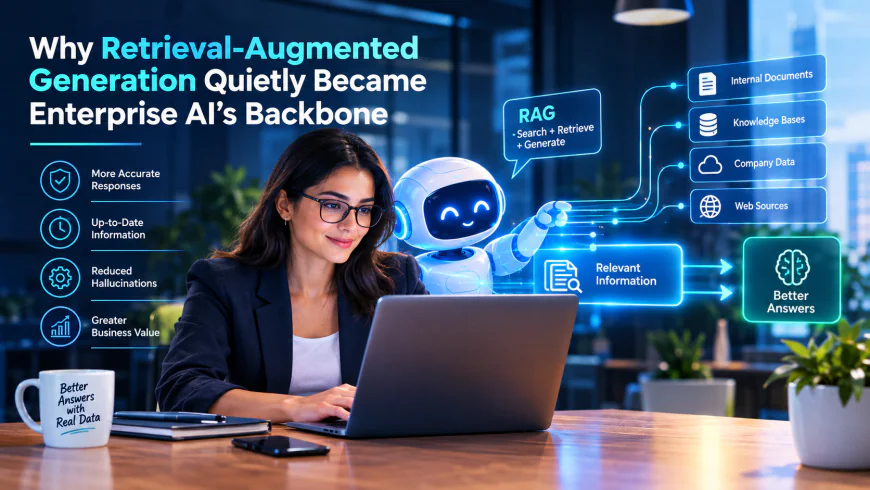
If you’ve used an internal AI tool at work over the past year that could accurately answer a question about your company’s own policies, contracts, or product documentation, there’s a good chance retrieval-augmented generation was doing the heavy lifting behind the scenes, even if nobody called it that.
RAG solves a problem that plain language models can’t solve on their own: they don’t actually know anything about your company. A general-purpose model was trained on public data up to a certain point and has no idea what’s in last week’s internal memo or this quarter’s updated pricing sheet. RAG fixes that by retrieving relevant company-specific information at the moment a question is asked, then feeding it to the model as context before it generates an answer. It’s a big part of why so many businesses now specifically look for an AI development company in New York that has real, hands-on RAG experience rather than a team that’s only worked with off-the-shelf chatbot templates.
It sounds simple in a sentence. Getting it right in production is a different matter entirely.
What RAG Actually Solves
Before RAG became standard practice, companies had two bad options for making AI systems aware of internal knowledge. The first was fine-tuning a model on internal documents, which is expensive, slow to update, and prone to the model quietly forgetting things or blending information incorrectly. The second was cramming everything into a single giant prompt, which runs into context limits fast and gets expensive at scale.
RAG splits the problem in two. A retrieval system finds the small number of relevant documents or passages for a given question. The language model then reasons over just those passages instead of trying to hold an entire knowledge base in its “head.” This keeps answers current, since updating the underlying documents updates the system’s knowledge immediately, with no retraining required.
Where Most RAG Implementations Go Wrong
The idea is simple enough that plenty of teams build a basic version quickly, get excited about early results, and then hit a wall once real users start asking real questions. A few failure patterns show up again and again.
Chunking documents badly. Splitting a document into arbitrary fixed-length chunks often cuts sentences and ideas in half, so the retrieval system returns fragments that are technically related to the query but missing the context needed to actually answer it.
Treating retrieval as a solved problem. Basic keyword or simple embedding search works fine for straightforward questions and falls apart on anything nuanced, like a question that requires combining information from three different documents or understanding an implicit reference.
No evaluation loop. Teams ship a RAG system, watch it work well in a demo, and never build a systematic way to measure answer quality against real user questions over time. Small degradations go unnoticed until someone gets a confidently wrong answer about something that actually matters.
Ignoring document freshness and access control. A RAG system that retrieves from an outdated document, or worse, from a document the requesting user shouldn’t have access to, creates real business and compliance risk that has nothing to do with model quality.
What a Well-Built RAG System Looks Like
The strongest implementations share a few common traits that are easy to describe but take real engineering discipline to execute consistently.
Chunking respects the actual structure of the source documents, keeping related ideas together rather than splitting on a fixed character count. Retrieval combines multiple techniques, such as semantic search alongside keyword matching, so the system catches both conceptual and exact-match questions. There’s a re-ranking step that scores retrieved passages for actual relevance before handing them to the model, since the first-pass retrieval often returns some noise alongside the useful results. And critically, there’s an ongoing evaluation process, using real or realistic questions, that catches quality regressions before users do.
Access control is baked into the retrieval layer itself, not bolted on afterward, so the system never even considers a document the current user isn’t permitted to see.
Beyond the Simple Question-Answering Use Case
RAG has moved well past internal chatbots at this point. It now underpins customer support systems that pull from product documentation and past ticket history simultaneously, sales enablement tools that retrieve the most relevant case study or pricing detail for a specific prospect, and compliance tools that check a document against the most current version of a regulatory framework before flagging issues. Agentic AI Development Services increasingly build RAG in as a foundational layer rather than a separate feature, since most useful agent actions depend on the agent first retrieving the right information before it decides what to do.
Measuring Whether Your RAG System Is Actually Working
Most teams measure the wrong thing. They watch whether the system produces an answer that sounds fluent and confident, which is a low bar that almost any modern language model clears easily. The harder and more useful question is whether the answer is grounded in the right source material and whether the retrieval step actually found the passages that mattered.
A practical evaluation setup involves building a test set of real questions with known correct answers and known correct source documents, then checking two things separately: did the retrieval step surface the right passages, and did the model use them correctly once it had them. Separating these two failure modes matters because the fix is completely different depending on which one is broken. If retrieval is missing the right passages, the fix is usually in the chunking or search strategy. If retrieval is working but the model still gets it wrong, the fix is usually in prompt design or how the retrieved context is formatted before it reaches the model.
Teams that skip this separation often end up chasing the wrong problem for weeks, tweaking prompts when the real issue was buried in how documents were chunked six steps earlier in the pipeline.
Frequently Asked Questions
Is RAG better than fine-tuning a model on company data?
For most enterprise use cases, yes. RAG keeps information current without retraining, is cheaper to maintain, and is easier to audit since you can see exactly which documents informed a given answer. Fine-tuning still has a role for teaching a model a specific tone or format, but it’s a poor fit for keeping facts up to date.
How much data do you need before RAG is worth building?
There’s no strict minimum, but RAG tends to show clear value once a company has enough internal documentation- at least a few hundred pages- that employees or customers routinely struggle to find answers manually.
Can RAG eliminate hallucinations?
It significantly reduces them by grounding answers in real retrieved content, but it doesn’t eliminate them. A well-designed system will also have the model clearly indicate when retrieved information doesn’t actually answer the question, rather than generating a plausible-sounding guess.
The Bottom Line
RAG became the default architecture for enterprise AI because it solves a real, practical problem, giving language models accurate, current, company-specific knowledge, without the cost and fragility of constant retraining. The systems that deliver real value are the ones where retrieval quality, evaluation, and access control get as much engineering attention as the language model itself.