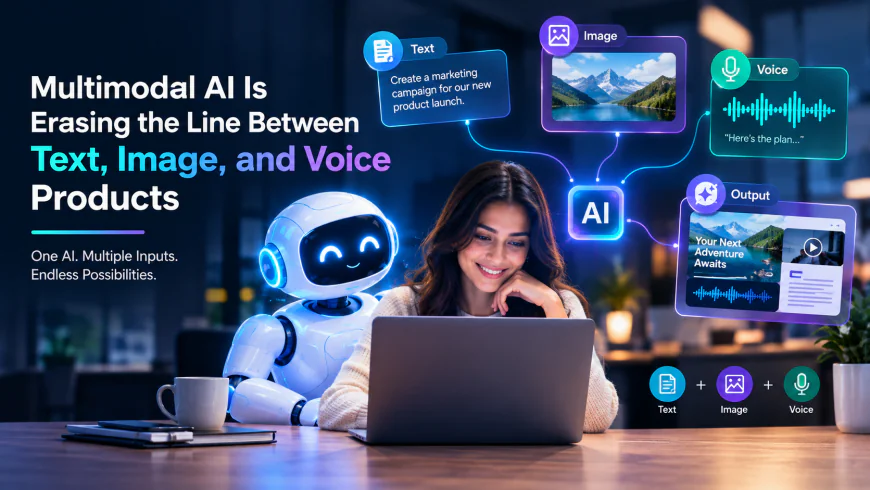
Multimodal AI Is Erasing the Line Between Text, Image, and Voice Products
Multimodal AI models now handle text, image, and voice together. Here’s what that convergence means for product design and where teams get it wrong.
 mobcoder ai
Not long ago, building an AI product meant picking a lane. Text products used language models. Image products used a separate class of vision models. Voice products used yet another stack entirely, usually stitched together from a speech-to-text step, a language model, and a text-to-speech step bolted on at the end, each one a potential point of failure. That separation is dissolving fast, and it’s changing what product teams are actually able to build.
Modern multimodal models can take an image, a snippet of audio, and a block of text as a single combined input and reason across all three at once, rather than processing them through disconnected pipelines. A user can point a phone camera at a broken appliance, describe the problem out loud, and get a coherent, contextual answer that references both what the model saw and what it heard. That single capability quietly closes gaps that used to require three separate engineering teams and three separate vendor relationships to approximate. It’s also reshaping the kind of work landing on the desk of any AI development company in New York, where clients increasingly ask for one coherent multimodal experience instead of three bolted-together tools.
Why This Matters More Than It Sounds
The obvious benefit is convenience: fewer steps for the user. The less obvious benefit, and the more important one for product teams, is that combining modalities inside a single model preserves context that gets lost when information passes between separate systems.
Consider a customer support scenario where someone sends a photo of a damaged product along with a written complaint. In a stitched-together pipeline, the image gets processed by a vision model that generates a text description, and only that description, stripped of everything not captured in words, gets passed to the language model handling the actual response. Details get lost in that handoff. A native multimodal model instead reasons directly over the pixels and the text together, catching details a two-step description might miss, like the specific way a component is cracked or the exact packaging visible in the background.
This same dynamic shows up in fields like healthcare intake, where a symptom description paired with a photo carries more diagnostic-adjacent information together than either would alone, and in field service, where a technician’s spoken description combined with a photo of an error screen gives a far more complete picture than either input in isolation.
Practical Applications Showing Up Right Now
Visual search and product discovery. Retail and e-commerce platforms are combining image search techniques with natural language refinement, letting a user upload a photo of something they like and then refine the results with a typed or spoken description like “in a warmer color” or “but with a lower heel.”
Quality inspection with narrated context. Manufacturing and logistics teams are using multimodal models to review photos of products or shipments alongside a worker’s spoken notes, catching discrepancies that a photo or a note alone might not surface clearly.
Accessibility tools. Multimodal models are powering tools that describe a scene from a photo in response to a spoken question, a meaningfully different and more useful experience than a generic, unprompted image caption.
Document processing with embedded visuals. Contracts, technical manuals, and reports that mix charts, diagrams, and text are now processed holistically instead of having their visual and textual content analyzed separately and reassembled afterward, which used to lose a lot of nuance.
Where Teams Get Multimodal Product Design Wrong
The most common mistake is treating multimodal capability as a feature to bolt onto an existing text-only product rather than rethinking the interaction model from the ground up. Adding an “upload an image” button to a chat interface that was designed entirely around typed text rarely produces a genuinely better experience. It usually just adds friction without changing the underlying interaction pattern in any meaningful way.
The teams building genuinely useful multimodal products start by asking what information is naturally easier to show than to describe, and what’s naturally easier to say than to type, then design the interaction around those realities instead of forcing everything through a text box because that’s the familiar default. A field technician talking through a problem while pointing a camera at it is a fundamentally different interaction than typing a support ticket, and the product should feel different too, not just accept a different input type through the same interface.
Cost and latency also deserve more attention than they typically get early on. Multimodal inference is generally more expensive and slower than text-only inference, and a product that processes every interaction through the heaviest available model, regardless of whether the task actually needs multimodal reasoning, will feel sluggish and burn through budget unnecessarily. The stronger pattern routes simple queries to lighter, faster models and reserves full multimodal reasoning for interactions that genuinely need it.
Building for Convergence Instead of Bolting It On
Teams that get this right usually start the same way: with an audit of every point in the current product where a user is forced to translate something naturally visual or spoken into typed text, because that’s the only input the system accepts. A user describing the color of a rash, the sound a car engine makes, or the layout of a room they want redesigned is being asked to compress rich, naturally non-textual information into words, often losing precision in the process.
Once those friction points are identified, the redesign question becomes concrete: what would this interaction look like if the system could actually see or hear what the user is trying to describe? Sometimes the answer is a modest addition, like allowing an optional photo upload. Other times it’s a more fundamental rethink of the entire interface, where voice or image becomes the primary input and text becomes the refinement layer instead of the other way around.
This is also where cross-functional collaboration matters more than it might seem. Multimodal product decisions sit at the intersection of engineering constraints, like inference cost and latency, and genuine user experience research into how people naturally want to communicate a given kind of information. Products designed by engineering alone tend to default to whatever’s technically easiest to ship, while products designed by user research alone sometimes propose interactions that are prohibitively expensive to run at scale. The strongest results come from teams that negotiate that tradeoff explicitly and early, rather than discovering the mismatch after launch.
Frequently Asked Questions
Is multimodal AI just image recognition with extra steps?
No. Image recognition classifies or labels what’s in an image in isolation. Multimodal AI reasons jointly across image, text, and sometimes audio inputs together, using the combined context to produce a single coherent answer rather than processing each input type separately.
Do multimodal models cost more to run than text-only models?
Generally yes, particularly for image and audio processing, which is why well-designed products route simpler queries to lighter models and reserve full multimodal reasoning for requests that actually need it.
What industries benefit most from multimodal AI right now?
Retail and e-commerce, field service and manufacturing, healthcare intake, and accessibility tooling are seeing some of the clearest early returns, largely because those use cases naturally combine visual and verbal or written information in ways a single-mode system can’t capture well.
Conclusion
Multimodal AI isn’t a novelty feature anymore; it’s becoming the default way people expect to interact with intelligent systems, by showing, saying, and typing in whatever combination feels natural for the moment. Product teams that rethink their interaction design around that reality, rather than treating multimodal input as an add-on to a text-first product, are the ones building experiences that actually feel like a genuine improvement rather than a gimmick.