How Multimodal AI Is Changing the Way Machines Understand the World
A practical look at multimodal AI, how it fuses images, text, and audio into one system, and what it means for search, support, and product design in 2026.
 mobcoder ai
For most of the last decade, an AI model was good at one thing. A vision model could tell you what was in a photo. A language model could hold a conversation. A speech model could transcribe audio. They rarely talked to each other, and if you wanted a system that could do all three, you were really stitching together three separate products and hoping the seams didn’t show.
That’s changed faster than most people outside the field have noticed. Early Image Search Techniques relied on matching visual features in isolation, color histograms, edge patterns, or tags a person typed in by hand. A photo of a red sneaker was findable only if someone had labeled it “red sneaker.” Today’s multimodal systems don’t need that label. They can look at the sneaker, read a product description, listen to a customer describe it out loud, and connect all three to the same underlying concept, because the model was trained to understand images, text, and audio as different windows into the same reality rather than three unrelated data types.
What Multimodal AI Actually Means
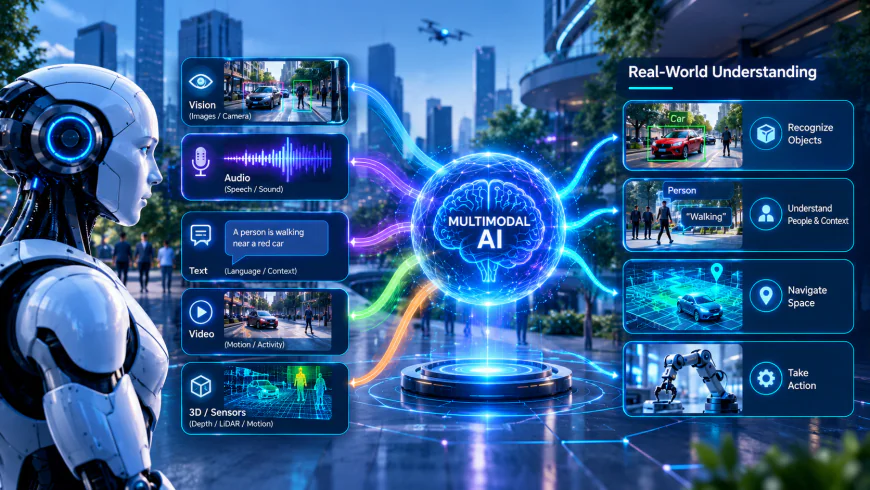
A multimodal model is trained on more than one type of input, and critically, it learns the relationships between them. Show it a picture of a golden retriever and the word “dog,” and it doesn’t just memorize that pairing. It builds a shared internal representation where the image, the word, and even a recording of a bark end up close together in the same mathematical space. That shared space is what lets the model reason across formats instead of translating clumsily between them.
This is a meaningfully different architecture from bolting a caption generator onto an image classifier. Models like GPT-4V, Gemini, and Claude’s vision capabilities were built from the ground up to accept mixed input, so you can hand them a screenshot, a spreadsheet, and a paragraph of instructions in the same request and get a coherent answer that draws on all three.
Why This Matters More Than It Sounds
The practical upside shows up in places people don’t expect. Customer support tools can now take a photo of a damaged product alongside a written complaint and route the ticket correctly without a human reading either one first. Retail search bars accept a picture instead of, or alongside, a text query, letting a shopper find “something like this” without knowing the product name. Accessibility tools can describe a scene to someone who can’t see it, in a tone that adjusts based on what the user is asking about.
Under the hood, a lot of this traces back to the same retrieval mechanics that power modern search. A model converts an image, a sentence, or a sound clip into a vector, a long list of numbers that captures its meaning, and then measures distance between vectors to find matches. It’s the same underlying math that improved Image Search Techniques over the past few years, just extended to handle several data types inside one shared space instead of one.
Where Businesses Are Actually Using It
A few patterns show up consistently across industries right now.
Visual commerce. Shoppers photograph an item they like and get matched to similar or identical products in a catalog, cutting out the guesswork of describing color, shape, or style in words.
Document intelligence. Insurance and legal teams feed in scanned forms, handwritten notes, and typed contracts together, and the model extracts structured data from all of them without separate pipelines for each format.
Field service and maintenance. A technician photographs a broken part, and the system cross-references the image against a manual and prior repair tickets to suggest a fix, combining visual diagnosis with written history in one step.
Content moderation. Platforms scan images, captions, and comment threads together to catch context that any single signal would miss, like a caption that changes the meaning of an otherwise harmless photo.
The Technical Challenges Nobody Skips
Multimodal systems are genuinely harder to build than single-format models, and it’s worth being honest about why.
Data alignment is the first hurdle. Training data needs paired examples, images with accurate captions, audio with correct transcripts, so the model learns real relationships rather than coincidental ones. Noisy or mismatched pairs quietly degrade accuracy in ways that are hard to catch during testing.
Compute cost is the second. Processing an image alongside text takes meaningfully more resources than text alone, which pushes teams toward careful decisions about what actually needs to be multimodal versus what can stay text-only.
Evaluation is the third, and probably the least discussed. It’s straightforward to measure whether a language model answers a question correctly. It’s much harder to measure whether a model correctly connected a photo to a paragraph of context, especially when the “correct” answer depends on nuance a benchmark can’t fully capture.
What to Ask Before You Build on Multimodal AI
Before committing engineering time to a multimodal feature, a few questions tend to separate projects that ship from ones that stall.
Does the use case genuinely need more than one modality, or would a well-built text or image pipeline solve 90 percent of the problem at a fraction of the complexity? Is there enough paired training data, or a viable path to collecting it, to fine-tune reliably? And does the team have a way to evaluate output quality that goes beyond spot-checking a handful of examples by hand?
Teams that skip these questions tend to end up with a demo that looks impressive and a production system that quietly underperforms. Teams that answer them honestly usually find that multimodal AI is worth the investment in a narrower set of places than the marketing suggests, but that in those places, it genuinely changes what’s possible.
Frequently Asked Questions
What is multimodal AI in simple terms?
It’s an AI system trained to understand and connect more than one type of input, such as images, text, and audio, instead of handling each format with a separate, disconnected model.
How is multimodal AI different from combining separate AI tools?
A true multimodal model learns shared relationships between formats during training, so it can reason across them. Stitching separate tools together usually means translating between formats at the surface level, which loses context in the process.
Is multimodal AI the same as computer vision?
No. Computer vision focuses specifically on interpreting images or video. Multimodal AI is a broader category that includes vision as one input type among several, paired with text, audio, or other data.
What industries benefit most from multimodal AI right now?
Retail and e-commerce, healthcare documentation, insurance claims processing, and customer support see some of the clearest early returns, largely because those workflows already combine images and written or spoken information.
If you’re evaluating whether a multimodal approach fits your product roadmap, it’s usually worth mapping the specific workflow first, since the architecture decisions look different depending on whether you’re building search, support automation, or something else entirely. Teams at Mobcoder AI work through exactly this kind of scoping as part of broader AI development services, helping businesses figure out where multimodal AI earns its complexity and where a simpler system will do the job just as well.