Computer Vision vs Image Recognition: What's the Difference and Why It Matters
Computer vision and image recognition are often confused. Learn how they differ and how each connects to modern image search techniques and product design.
 mobcoder ai
These two terms are often used interchangeably, so most people assume they mean the same thing. They do not, and the difference is not just academic. It shapes how a product team scopes a project, what model they actually need, and what a system can and can't do once it is built.
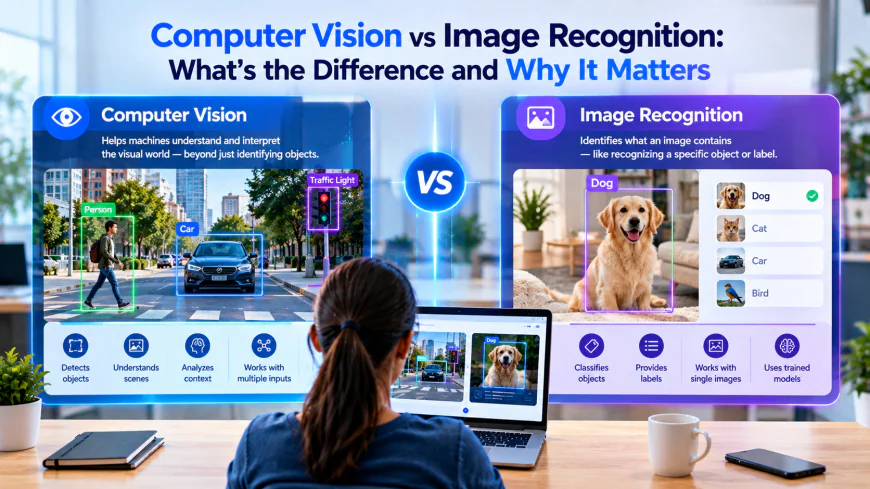
Image recognition is one specific task: identifying what is in a picture. Computer vision is the much broader field that image recognition belongs to, covering everything from tracking motion across video frames to measuring distances in 3D space. Understanding where one ends and the other begins helps explain why some image search techniques work well for simple product lookups but fall short for more complex visual tasks.
This distinction matters most when a team is deciding what kind of system to actually build, since the two require different models, different data, and often very different levels of engineering effort.
What Image Recognition Actually Does
Image recognition answers a narrow, specific question: what is this, or what is in this? A model trained for this task looks at a photo and outputs a label or a set of labels, a dog, a coffee cup, a stop sign, often with a confidence score attached to each guess.
This is the technology behind features like automatically tagging photos by content, filtering inappropriate images on a platform, or identifying a product category from a photo. It is a well-understood, mature task, and pre-trained models handle common categories reasonably well without much custom work.
What Computer Vision Covers Beyond That
Computer vision is the umbrella field, and image recognition is just one task within it. Object detection locates and draws boundaries around multiple objects within a single image, not just labeling the overall scene. Segmentation goes a step further, identifying the exact pixels that belong to each object rather than a rough bounding box.
Then there is tracking, following an object's movement across video frames, depth estimation, judging distance and spatial relationships from a 2D image, and pose estimation, mapping the position of a body or object's joints and orientation. Self-driving cars, industrial quality inspection, and augmented reality apps all depend on these more advanced computer vision tasks, not just basic recognition.
Why This Distinction Changes What Gets Built
A team that actually needs object detection but scopes a project as simple image recognition will end up with a model that can say "this photo contains a car" but cannot say where the car is in the frame or how many there are. That gap only becomes obvious once the feature is already in testing, which makes it an expensive mistake to catch late. Rewriting a project's scope mid-build usually means redoing data labeling, retraining a model from a different starting point, and, in many cases, pushing back a launch date that stakeholders were already counting on.
The reverse problem happens too. Building full computer vision capability, tracking, segmentation, depth estimation, for a task that only needed basic recognition wastes engineering time and computational budget on capability the product will never use. Getting this scoping right early is one of the more overlooked factors in whether an AI feature ships on time and on budget.
How This Maps to Search Specifically
Most consumer-facing visual search features rely primarily on image recognition and a related task called image similarity, rather than the full range of computer vision capability. A shopper searching by photo generally needs the system to identify what an item is and find similar items, not track its movement or estimate its depth in 3D space.
More advanced use cases push further into computer vision territory. A retail app that lets a shopper photograph a room and place furniture into it using augmented reality needs depth estimation and spatial understanding on top of basic object recognition, which is a meaningfully bigger engineering lift than search alone.
Choosing the Right Scope for a Project
The practical starting point for any team is writing down, specifically, what the system needs to answer. "What is in this photo" is image recognition. "Where exactly is each object, and how many are there" is object detection. "How far away is this object, and how should a virtual item be placed relative to it" moves into full computer vision territory.
Getting this right early tends to save significant rework later, since the model architecture, training data requirements, and infrastructure needs differ substantially between these tasks, even though all of them fall under the broad umbrella of "AI that understands images."
A Simple Way to Think About the Spectrum
It helps to picture these tasks on a spectrum of increasing complexity. Classification sits at the simple end, answering only whether an image belongs to a category at all. Recognition and detection sit in the middle, identifying and locating specific objects. Segmentation, tracking, and depth estimation sit toward the complex end, requiring the system to understand fine-grained spatial and temporal detail.
Most business applications only need to move as far along that spectrum as the actual use case demands. A product catalog search tool rarely needs to sit at the complex end, while an autonomous vehicle or an industrial robotics application almost always does. Matching ambition to actual need, rather than defaulting to the most advanced approach available, tends to produce faster, cheaper, and more reliable results.
It also helps when communicating with stakeholders outside engineering. Describing a project honestly in terms of where it sits on this spectrum, rather than using "AI" as a single catch-all term, sets clearer expectations for what the finished system will and will not be able to do. Teams that skip this step often end up managing disappointment later, when a stakeholder assumes a simple recognition feature includes capability it was never built to have.
Frequently Asked Questions
Is computer vision the same as image recognition?
No. Image recognition is one specific task, identifying what is in a picture, while computer vision is the broader field that includes recognition along with tasks like object detection, segmentation, tracking, and depth estimation.
Which one powers most visual search features?
Most consumer visual search relies primarily on image recognition and image similarity matching, rather than the full range of computer vision capabilities like tracking or depth estimation.
Why does the distinction matter for a business building an AI feature?
Because scoping a project incorrectly, choosing simple recognition when object detection is actually needed, or the reverse, leads to either a feature that cannot do what was promised or wasted engineering effort on unused capability.
How do object-based visual queries relate to object detection?
Basic photo-based search tools mostly need recognition and similarity matching, while more advanced search experiences that need to locate multiple items within one photo rely on object detection as well.
What is a simple way to decide which capability a project actually needs?
Write down the exact question the system needs to answer. "What is in this photo" points to recognition, while "where exactly is each object" points to object detection or broader computer vision.
Do most business applications need the most advanced computer vision capability available?
No. Most only need to move as far along the complexity spectrum as the actual use case requires, and defaulting to the most advanced approach usually adds unnecessary cost and complexity.