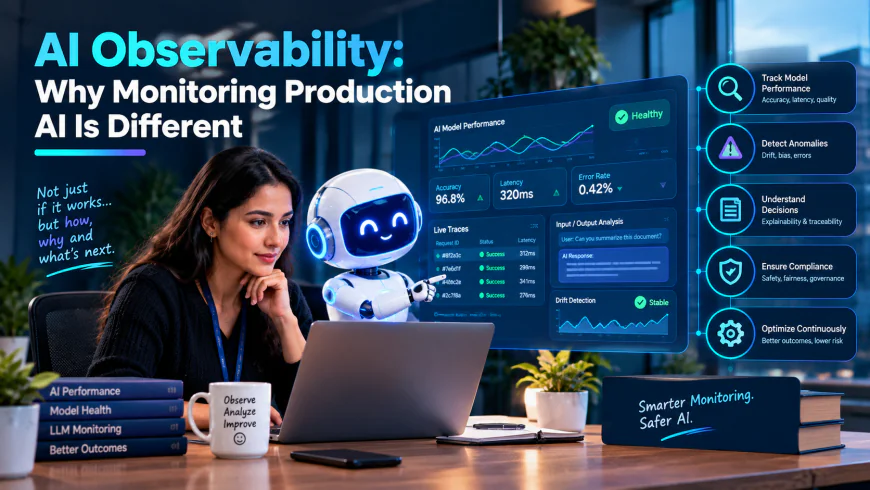
AI Observability: Why Monitoring Production AI Is Different
What AI observability actually means, why traditional software monitoring falls short for AI systems, and what businesses need to track once a model is live.
 mobcoder ai
Traditional software monitoring answers a fairly binary question: is the system up, and is it responding within an acceptable time? That framework has served engineering teams well for decades, and most monitoring tools were built entirely around it. AI systems uncomfortably break that framework, because a model can be up, fast, and returning a perfectly formatted response that is also completely wrong, and none of the traditional monitoring signals would catch it.
This gap is exactly why AI observability has become its own discipline rather than an extension of existing tools. An AI Development Company in Seattle recently onboarded a client whose support chatbot had a perfect uptime record for three straight months, according to their existing monitoring stack, while quietly giving incorrect refund policy information to customers the entire time. The system was never down. It was just wrong, and nothing in their monitoring was built to notice that difference.
What AI Observability Actually Tracks
AI observability extends traditional monitoring with a layer specifically focused on output quality and model behavior, not just system health. A few categories make up most of what a mature setup tracks.
Output quality and accuracy. Is the model’s response actually correct, relevant, and appropriate for the input it received? This usually requires some combination of automated evaluation against known-good answers, sampling and human review, and tracking downstream signals like whether a user had to rephrase their question or escalate to a human.
Drift. A model’s performance can degrade over time even without any code changes, because the real-world data it’s now seeing has shifted away from what it was trained or evaluated on. A customer support model trained before a major product launch, for instance, may start performing noticeably worse on questions about the new product simply because it’s outside its original training distribution.
Latency and cost per request, broken down meaningfully. A blended average latency number hides a lot. What matters more is latency by request type, since a system that’s fast on 95 percent of queries and painfully slow on the remaining 5 percent has a real problem a single average number won’t surface.
Hallucination and confidence signals. For generative systems specifically, tracking how often a model produces confident-sounding but unsupported claims, and whether it has any internal signal of uncertainty it’s failing to surface to the user.
Usage patterns and edge cases. What are people actually asking the system, and how much of that falls outside what it was designed and tested for? This is often where the earliest warning signs of a real problem show up, well before it becomes visible in aggregate accuracy metrics.
Why This Is Genuinely Harder Than Traditional Monitoring
Traditional software has a clear definition of correct behavior: a function either returns the right value or it doesn’t, and that’s usually testable in a deterministic way. AI outputs, especially from generative models, often don’t have a single correct answer, which makes defining “wrong” itself a real engineering and product problem before any monitoring tooling even gets built.
There’s also a delayed feedback problem. A traditional software bug usually surfaces quickly: an error gets thrown, a request fails visibly. An AI system giving subtly wrong answers can run for weeks looking completely healthy by every traditional metric, with the damage only becoming visible once someone happens to spot a pattern of bad outcomes or a customer complaint traces back to it.
What a Practical Observability Setup Actually Includes
Teams that build this well tend to combine a few specific practices rather than relying on one dashboard to catch everything.
Golden test sets that run continuously. A curated set of known inputs with expected outputs, run regularly against the live system in production, catches regressions from model updates, prompt changes, or upstream data shifts before they affect real users at scale.
Sampling and structured human review. Even with automated evaluation, a regular process for humans to review a sample of real production outputs, not just test cases, catches issues that automated checks miss, especially nuanced quality problems that are hard to define programmatically.
Clear escalation thresholds. Defining in advance what output quality or drift metric triggers an alert, and who’s responsible for responding, so a slow degradation doesn’t quietly continue for months because nobody was specifically watching for it.
Feedback loops from real usage. Tracking signals like user rephrasing, escalation to a human, or explicit negative feedback, and feeding that back into evaluation, closes the loop between what’s actually happening with real users and what the observability system is measuring.
This same philosophy- narrow, continuous, automated checks that escalate to deeper investigation only when something looks genuinely anomalous- is the same architectural pattern behind purpose-built monitoring tools like Server Intelligence Agent, which applies it to infrastructure telemetry rather than model output quality. The underlying design logic transfers well between the two domains, even though what’s being monitored is completely different.
Observability for Agents Specifically
The stakes rise further once an AI system isn’t just generating text but actually taking action, sending messages, modifying records, executing multi-step workflows. Observability for an agent needs to track not just whether the final outcome was correct, but the full reasoning path that led there: what tools it called, what information it had access to, and what alternatives it considered along the way. Without that level of detail, diagnosing why an agent took a specific wrong action after the fact becomes close to impossible, since the final log entry alone rarely explains the reasoning behind it.
Starting Small Without Overbuilding a Monitoring Stack
Teams new to AI observability sometimes assume they need a full, purpose-built platform before they can start measuring anything meaningfully, and that assumption often delays getting any visibility at all. A more practical starting point is picking the single highest-risk AI feature in production, defining what “wrong” looks like for that specific feature in concrete terms, and building a small, regularly reviewed sample process around it before trying to instrument everything at once. That narrow start tends to surface real problems faster than a comprehensive dashboard nobody has time to actually watch closely.
Frequently Asked Questions
What is AI observability in simple terms?
It’s the practice of monitoring not just whether an AI system is technically running, but whether its outputs are actually accurate, relevant, and consistent over time, which traditional uptime and latency monitoring doesn’t capture.
How is AI observability different from traditional application monitoring?
Traditional monitoring focuses on system health, uptime, latency, and error rates. AI observability adds a layer focused on output quality, accuracy drift, and behavior over time, since an AI system can be technically healthy while producing consistently wrong or degrading results.
What is model drift and why does it matter?
Drift is when a model’s real-world performance degrades over time because the data it now encounters differs from what it was trained or evaluated on, even though no code or configuration has changed. It matters because it can silently erode accuracy without triggering any traditional alert.
Do small AI features need the same level of observability as large ones?
The level of investment should scale with the risk and volume of the feature. A low-stakes internal tool used occasionally needs far less monitoring rigor than a customer-facing system handling thousands of requests a day with real business consequences.
Building observability into an AI system from the start is significantly easier than retrofitting it after a quality problem has already gone unnoticed for months. It’s a core part of what Mobcoder AI builds into deployments under its Agentic AI development services, so teams can actually see what their AI systems are doing in production, not just assume it’s working because nothing crashed.