Agentic AI is breaking traditional compute assumptions, here's why
Discover how AI agents impact GPU infrastructure, CPU requirements, memory and cloud costs. Learn how to optimize AI agent workloads and reduce GPU idle time.
 Prateek
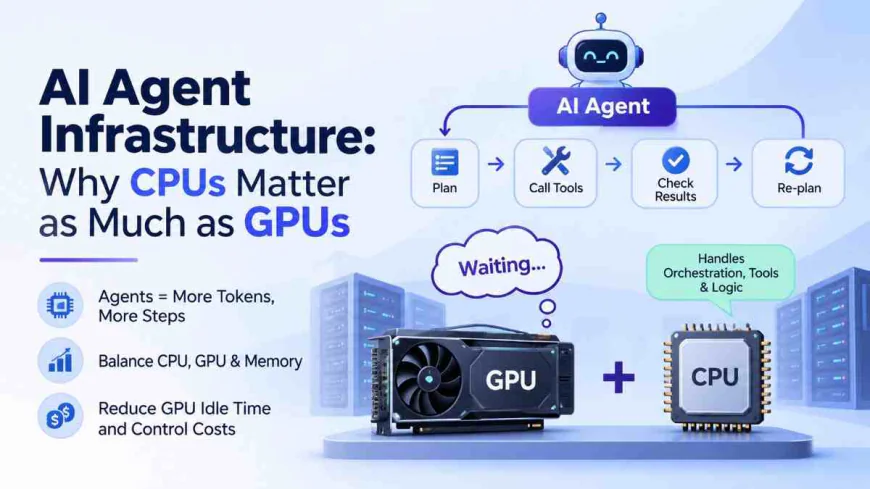
Here is a strange thing about AI agents: the expensive GPU is often the part waiting around.
For three years the infrastructure question was simple. How many GPUs do we need? With agents, that question stops being enough, because a lot of the time the GPU is idle while something else catches up. Here is what changes, with the numbers that matter, so you can plan for it before the bill teaches you.
What assumptions does agentic AI break?
Three assumptions that most AI infrastructure was built around.
|
Old assumption |
What agents do instead |
|
One request means one model call |
One request becomes a loop of plans, tool calls and checks |
|
The GPU is the bottleneck |
The CPU and the tools often are |
|
Demand is steady and predictable |
Demand is bursty, and no two tasks cost the same |
Everything else in this article follows from those three rows.
Why do AI agents use so many more tokens than a chatbot?
Because one request becomes a loop. The agent plans, calls a tool, reads the result, re-plans, checks its own work and tries again, and each step re-sends the growing context.
A 2026 Gartner analysis reportedly found that agentic models need 5 to 30 times more tokens per task than a standard chatbot. One illustrative example from networking vendor Ciena shows a 50-token request fanning out into a 50,000-token job as it spreads across agents. One analysis puts a multi-step agent at roughly $0.10 to $1.00 per completed task, which is far above a single chat reply.
Why does this matter for budgeting?
Because you can no longer budget per request. A request that takes three steps and one that takes thirty look identical from the outside and cost very different amounts. Budget per completed task, and cap how many steps and tokens a single task is allowed to use.
Why is the CPU suddenly part of the AI infrastructure story?
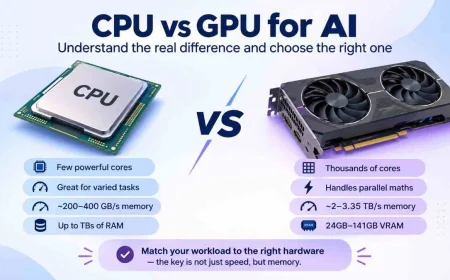
Because everything between the model calls runs on the CPU. Orchestration, tool routing, running code, parsing results and checking whether the task is done are all CPU work. The GPU only does the thinking part.
Spheron's 2026 sizing guide gives a clear picture: a 10-step task with 3 tool calls per step means about 30 rounds of CPU-heavy work for every 10 GPU inference passes. The CPU does three times the turns.
|
Workload |
Rough vCPUs per GPU to start with |
|
Plain LLM inference, no tool calls |
4 to 8 |
|
Agentic pipelines |
8 to 24 |
|
Reinforcement learning rollouts |
Up to 64 |
The wider industry is moving the same way. Training clusters were built around roughly 1 CPU for every 8 GPUs. Red Hat, citing Intel, describes agentic deployments converging toward 1:1, with some customers deploying several CPUs per GPU. Arm estimates that a gigawatt of AI capacity needs about 30 million CPU cores today and around 120 million in the agent era. Nvidia's Vera Rubin NVL72 rack already pairs 72 GPUs with 36 CPUs.
What happens to your GPU when the CPU cannot keep up?
It sits idle, and you keep paying GPU rates for it. In many agentic workflows, the wait on tools and orchestration can outweigh the time the model spends running. This is the same trap as an idle instance overnight, just happening hundreds of times a day inside a single task.
Why is capacity planning harder with agents?
Because the demand is uneven in two ways at once.
-
Variable depth: one task may finish in three steps, another in thirty, and you cannot know in advance
-
Growing context: agents carry their history forward, so memory use climbs as a task runs, which is what the KV cache is for
-
Concurrency: many tasks running at the same time multiply both of the above
The sizing advice that follows: plan for sustained concurrency and KV cache growth, not single-request speed.
Does this mean you need more GPUs?
Not necessarily. You usually need more CPU and memory per GPU, while the GPU itself is sized by the model as usual. Buying more GPUs to fix an agent that is waiting on its tools just adds more idle GPUs.
What does AI agent infrastructure actually need?
Put together, ai agent infrastructure looks less like a GPU farm and more like a balanced system. The pieces that matter:
-
GPU nodes with enough CPU, since the ratio per GPU matters as much as the GPU model
-
Generous RAM, for context, caches and tool execution
-
Fast storage and networking, because agents keep reading and writing shared state
-
Isolated places to run tools, so code an agent writes cannot reach your real systems
-
Elastic capacity, since bursts are normal and a fixed fleet is either idle or overrun
-
Token and cost tracking, per task and per agent, not just per month
If a provider only lists the GPU on its pricing page, check what CPU and memory come with it. For agent workloads, that is half the performance.
What does a waiting GPU look like in money terms?
Here is an illustrative case with simple numbers. Say you rent one GPU at $2 an hour. An agent task takes one minute from start to finish, but the model only works for fifteen seconds of it. The rest is tool calls and orchestration.
That minute costs about 3.3 cents of GPU time, and a quarter of it does real inference. If the GPU is kept busy with other tasks while one waits, the same minute can carry up to four tasks. The hardware did not change. Only the scheduling did.
How can you control the cost of running agents?
Start with the changes that cost nothing.
-
Set a token budget per task, enforced where requests enter your system
-
Cap the number of steps, so a confused agent cannot loop all night
-
Measure cost per completed task, not cost per model call
-
Check GPU utilisation against wall-clock time, to see how long the GPU spends waiting
-
Right-size CPU per GPU, and do not pair expensive GPUs with a starved CPU
-
Batch and queue work where users do not need an instant answer
Conclusion
Agents turn inference into a loop, and that loop leans on CPUs, memory and the network as much as on the GPU. Plan for tokens per task, balance your CPU and GPU, and measure how much time the GPU actually spends working. The teams that do will spend less and scale further than the ones still counting only GPUs.
Note: figures here are as reported in October 2026 industry analyses and will keep moving. Treat the ratios as starting points, not rules.
Frequently asked questions
Do AI agents still need GPUs?
Yes, for the model itself. But the orchestration around the model runs on CPUs, and in some agent workloads the CPU side becomes the limit.
How many vCPUs per GPU should I start with?
For agentic pipelines, around 8 to 24 is a common starting point, against 4 to 8 for plain inference. Treat that as a first guess and tune it by measuring how often your GPU waits.
Is this only a problem for large companies?
No. Even a small team with one agent sees it as soon as tool calls start to dominate. If your GPU is billed by the hour and half of that time it is waiting, you are paying for the wait.