Accessibility and Visual Search: How AI Is Helping Blind and Low-Vision Users "See" Images
AI is helping blind and low-vision users understand images through description tools. See how these image search techniques improve digital accessibility.
 mobcoder ai
For someone who is blind or has low vision, the internet has always been a heavily visual place built with limited regard for how it would be experienced without sight. Product photos, charts, memes, and screenshots routinely carry information that a screen reader simply cannot access unless someone specifically wrote a description for it, and most of the time, nobody did.
AI has started closing that gap in a genuinely meaningful way. Tools that can look at a photo and generate a spoken description in real time are giving blind and low-vision users a level of independent access to visual content that simply did not exist a decade ago. The same underlying image search techniques that power product discovery and reverse image lookup are now being repurposed for description and understanding rather than matching.
This overlap between commercial visual search and accessibility technology is not a coincidence. Both rely on a system's ability to genuinely understand what is happening in an image, not just detect that an image exists.
What These Tools Actually Do
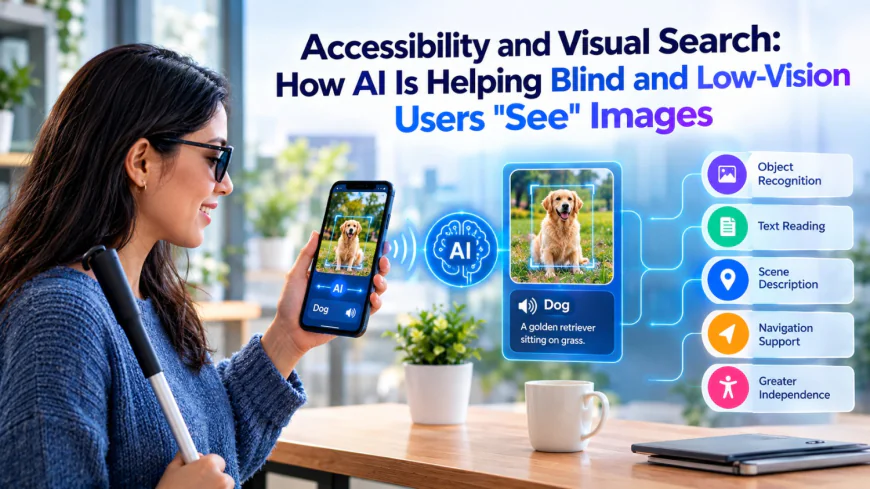
The core capability is image captioning: a model looks at a photo and generates a natural-language description of what it contains. Early versions of this technology produced fairly generic output, "a person standing near a building", but modern systems can describe detail, colors, relative positions, text within the image, and context that makes the description genuinely useful rather than just technically accurate.
Some tools go further, allowing a user to ask follow-up questions about a specific photo rather than receiving a single static description. A user might ask what color a piece of clothing is, whether there is text visible in a photo, or how many people are in a group shot, and get a direct answer rather than having to parse a general summary for that detail.
Where This Shows Up in Everyday Use
Social media platforms increasingly generate automatic alt text for photos that were never manually described by the person who posted them, giving screen reader users at least a baseline understanding of an image instead of hearing nothing or just a filename. Shopping apps use similar description tools to help a blind shopper understand a product photo well enough to make a purchase decision independently.
Navigation is another significant use case. Apps that can describe a scene in real time, reading a street sign, identifying an obstacle, describing what is on a restaurant menu photographed on a phone, are giving users a level of situational independence that previously required asking another person for help.
Why This Overlaps With Commercial Visual Search
Underneath the surface, an accessibility description tool and a product visual search feature often rely on very similar model architectures, systems trained to understand the relationship between images and language well enough to move fluidly between the two. A model good at describing a photo in detail is frequently also good at matching that photo against similar products or verifying what it depicts.
This shared foundation means improvements made for one purpose often benefit the other. A company investing in better photo-recognition search technology for commerce is frequently building capability that, with relatively modest additional work, can also power meaningfully better accessibility features, rather than these being two entirely separate engineering efforts.
Where the Technology Still Falls Short
Accuracy remains an issue for detail that matters a great deal to the person relying on it. A description that gets a color slightly wrong or misses a small but important detail in a product photo can lead to a genuinely frustrating or costly mistake, in a way that a similar error in a casual browsing context would not. Trust has to be earned carefully in this context, since the cost of an inaccurate description is much higher for someone who cannot independently verify it visually.
Cultural and contextual nuance is another limitation. A model might accurately describe the literal contents of an image while completely missing context a sighted person would immediately pick up on, a facial expression, a culturally specific object, or the significance of a particular setting, which limits how complete these descriptions really are even when they are technically correct.
What Comes Next
The direction is toward richer, more interactive description, not just a static caption but an ongoing conversation about an image, answering follow-up questions and adjusting detail based on what a user actually wants to know. As these systems improve, the line between an accessibility tool and a general-purpose visual search assistant is likely to blur further, since both are ultimately solving the same underlying problem: helping a person understand what an image contains and means.
For businesses, this points toward a practical argument for investing in high-quality image understanding beyond pure commercial use cases. Accessibility is not a separate feature bolted onto a product. It is frequently a direct byproduct of building genuinely good visual AI in the first place.
What Businesses Can Do to Support This
Writing genuinely descriptive alt text for product and content images, rather than treating it as a compliance checkbox, benefits both screen reader users directly and any AI system evaluating that image for other purposes, including search and discovery. This is one of the rare cases where accessibility work and commercial visibility point in exactly the same direction.
Testing product and content pages with an actual screen reader periodically, not just an automated accessibility scanner, tends to surface gaps that automated tools miss entirely, particularly around images that carry meaningful information but were never given a proper description in the first place.
Involving people who actually rely on these tools day to day, rather than relying solely on internal assumptions about what makes a good description, consistently produces better results than accessibility work done in isolation from the community it is meant to serve. Even a small, ongoing feedback loop with real users tends to surface issues that internal testing, however careful, reliably misses.
Frequently Asked Questions
How does AI help blind users understand images?
Through image captioning models that generate natural-language descriptions of a photo's content, and increasingly, tools that let a user ask follow-up questions about specific details within that image.
Are accessibility description tools related to commercial visual search technology?
Yes. Both often rely on similar underlying models trained to understand the relationship between images and language, so improvements in one area frequently benefit the other.
What is the biggest limitation of current image description tools?
Accuracy on fine detail and missing cultural or contextual nuance that a sighted person would immediately notice, even when the literal description is technically correct.
Do these tools work equally well across all types of images?
No. They tend to perform best on clear, well-composed photos and less reliably on cluttered scenes, unusual angles, or images containing small but important text or detail.
Where do blind and low-vision users encounter this technology most often?
On social media through automatic alt text, in shopping apps for product understanding, and in navigation tools that describe surroundings or read signs and menus in real time.
Is this technology likely to improve further?
Yes. The trend is toward more interactive, conversational description rather than a single static caption, allowing users to ask specific follow-up questions about an image.
What can businesses do to support this beyond commercial features?
Writing genuinely descriptive alt text and periodically testing pages with an actual screen reader tend to surface gaps that automated accessibility scanners often miss.