Synthetic Data in AI Training: Why Companies Generate Their Own
Why more businesses are generating synthetic data to train and fine-tune AI models, where it works well, where it doesn’t, and how to avoid the common pitfalls.
 mobcoder ai
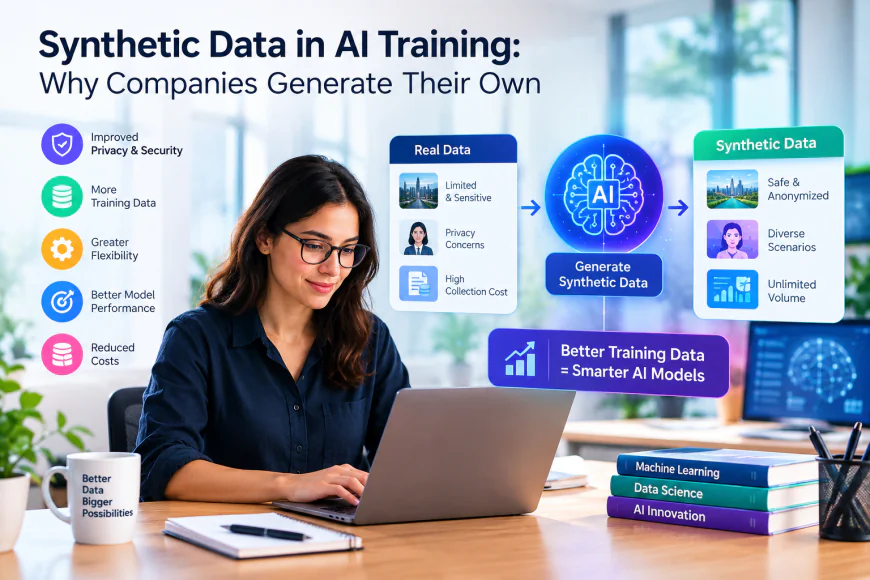
Every team that’s tried to fine-tune a model on real company data eventually runs into the same wall: there isn’t enough of it, it’s messy, or using it raises privacy concerns nobody wants to own. A fraud detection model needs thousands of examples of fraudulent transactions, which are rare by definition. A medical imaging model needs labeled scans of a specific rare condition, which might not exist in usable volume anywhere. The answer a growing number of teams have landed on is generating the data themselves, synthetically, rather than waiting to collect enough real examples.
This isn’t a fringe technique anymore. An AI Development Company in Seattle working with a regional insurer recently built a fraud detection model almost entirely on synthetic transaction data, because real fraudulent examples in the client’s history were too sparse and too sensitive to use directly for training at scale. The synthetic dataset was built to statistically resemble real fraud patterns without containing any actual customer records, solving the volume problem and the privacy problem in the same step.
What Synthetic Data Actually Is
Synthetic data is artificially generated information that mimics the statistical properties of real data without being drawn directly from real records. It can take many forms: simulated transactions, generated text conversations, computer-generated images, or artificially constructed sensor readings, depending on what the model needs to learn from.
The key property that makes synthetic data useful isn’t that it’s fake, it’s that it’s designed to preserve the patterns a model needs to learn while controlling exactly what information goes into it. A well-built synthetic dataset can be tuned to include more examples of a rare but important scenario than would ever naturally occur in real data, correcting for the class imbalance that quietly undermines a lot of real-world training sets.
Why Teams Reach for Synthetic Data
Scarcity of real examples. Rare events, equipment failures, fraud, rare disease presentations, are by definition uncommon in real data, which makes it hard for a model to learn their patterns reliably. Synthetic generation can produce as many examples as needed, calibrated to reflect realistic variation.
Privacy and compliance. Using real customer, patient, or financial data for training carries regulatory weight, and in some cases legal restrictions, that synthetic data sidesteps entirely, since it was never tied to a real individual in the first place.
Labeling cost. Real data usually needs to be manually labeled before it’s useful for training, which is slow and expensive at scale. Synthetic data can often be generated with labels already attached, since the generation process knows exactly what it produced.
Edge case coverage. Real-world data collection is passive, you get whatever happened to occur. Synthetic data generation is deliberate, letting a team specifically construct examples of unusual situations a model needs to handle but that real data might not have captured yet in sufficient volume.
This dynamic played out clearly in the evolution of Image Search Techniques, where early visual search models were often trained partly on synthetically generated or augmented images, rotated, recolored, recombined, specifically to teach the model robustness to variations that a limited real photo dataset wouldn’t fully cover on its own.
Where Synthetic Data Works Well
Tabular and structured data, transactions, sensor readings, log data, tends to generate convincingly, because the statistical relationships between fields are often well understood and mathematically modelable. Fraud detection, demand forecasting, and anomaly detection systems have all benefited significantly from synthetic augmentation of rare-event training data.
Simulation-heavy domains, robotics, autonomous vehicles, industrial process control, lean on synthetic data heavily because real-world testing of dangerous or expensive scenarios is impractical at the volume needed for training. A self-driving system can encounter a simulated pedestrian crossing scenario ten thousand times in an afternoon in a way it never could safely on real roads.
Data augmentation for computer vision, generating variations of existing real images, remains one of the most mature and reliable applications, since the technique has been refined over many years and the risk of the synthetic examples diverging meaningfully from reality is comparatively low.
Where It Falls Short
Highly nuanced human language and behavior are much harder to synthesize convincingly. Generated customer service conversations, for instance, often lack the genuine unpredictability and idiosyncrasy of real human communication, which can leave a model trained heavily on synthetic conversational data brittle when it encounters the messiness of actual customers.
There’s also a subtle risk of the synthetic data reflecting the biases or blind spots of whatever process generated it, rather than the biases of real-world data specifically. If the generation process itself has gaps in what it can realistically simulate, a model trained on it inherits those same gaps, just less visibly, because the dataset looks complete and well-balanced on the surface.
Validation is harder than it sounds. It’s tempting to assume synthetic data is “correct” because it was deliberately constructed, but a model trained purely on synthetic data still needs to be validated against real-world examples before deployment, since the whole point is that it eventually needs to perform on real, not synthetic, inputs.
Getting Synthetic Data Right
Teams that use synthetic data well treat it as a supplement to real data, not a full replacement, blending synthetic examples in to correct for specific known gaps, rare events, sensitive categories, underrepresented edge cases, rather than trying to generate an entire training set from scratch. They also invest specifically in validating model performance against a held-out set of real data, not synthetic data, since that’s the only reliable signal of how the model will actually perform once deployed.
Frequently Asked Questions
What is synthetic data in AI training?
It’s artificially generated data designed to statistically resemble real-world data without being drawn from actual records, used to train or fine-tune models when real data is scarce, sensitive, or expensive to label.
Is synthetic data as good as real data for training AI models?
It depends on the use case. For structured data and specific rare-event augmentation, it can be highly effective. For nuanced human behavior and language, it generally works best as a supplement to real data rather than a full replacement.
Does synthetic data solve privacy concerns in AI training?
It significantly reduces them, since synthetic data isn’t tied to real individuals, but teams still need to ensure the generation process itself doesn’t inadvertently reproduce identifiable patterns from the real data it was modeled on.
Why is synthetic data especially useful for fraud and rare-event detection?
Because genuine examples of rare events are, by definition, uncommon in real data, which makes it hard for a model to learn reliable patterns. Synthetic generation can produce enough calibrated examples to give the model adequate signal to learn from.
Deciding whether synthetic data genuinely solves a specific training problem, and building a generation process that actually holds up under validation, is a task worth scoping carefully before committing engineering time to it. It’s a piece of the broader model development work Mobcoder AI takes on as part of its AI development services, helping teams figure out where synthetic data earns its complexity and where collecting more real data is still the better path.