How AI Agents Are Quietly Taking Over Enterprise Workflows
See how autonomous AI agents are automating enterprise workflows in 2026, from operations to customer support, and what it means for your team.
 mobcoder ai
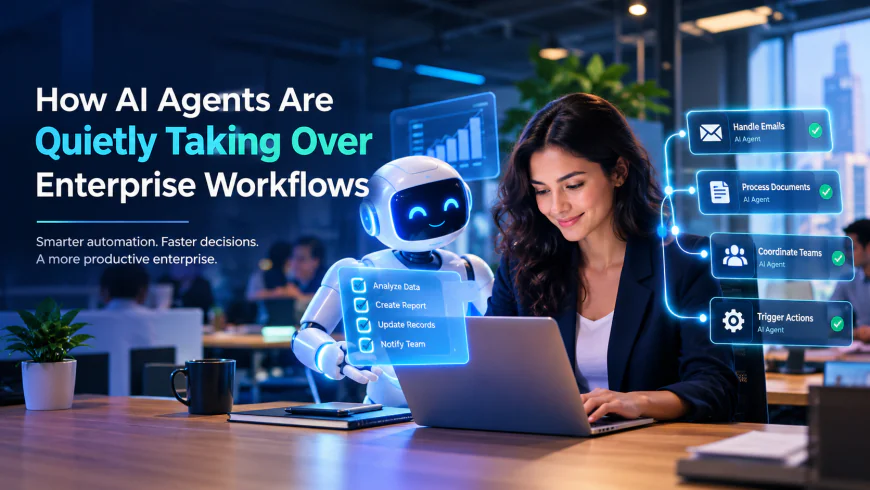
Most people still picture AI as a chatbot that answers questions when prompted. That picture is already out of date. Inside a growing number of enterprises, AI agents are no longer waiting for a question. They are opening tickets, reconciling invoices, scheduling follow-ups, and flagging anomalies on their own, then reporting back only when a human decision is genuinely needed.
This shift matters most in cities with dense concentrations of finance, media, and professional services firms, where the volume of repetitive coordination work is enormous. It is one reason an AI development company in New York is fielding a very different kind of request this year than it was two years ago. Clients are not asking for a smarter search bar anymore. They are asking for a system that can act.
The distinction between “AI that answers” and “AI that acts” sounds subtle, but it changes almost everything about how a system needs to be built, tested, and governed.
From Assistants to Agents
A traditional AI assistant is reactive. You type a question, it returns an answer, and the interaction ends. An AI agent is different in three specific ways:
-
It can break a goal into a sequence of steps without being told each step individually.
-
It can call external tools and APIs, such as a CRM, a billing system, or an internal database, to gather information or take action.
-
It can evaluate the outcome of its own actions and decide whether to continue, retry, or escalate to a person.
That last point is the one companies underestimate. An agent that can act but cannot judge the quality of its own output is a liability, not an asset. The real engineering work in agentic systems isn’t the action-taking itself; it’s building reliable checkpoints so the agent knows when it’s out of its depth.
Where Agents Are Actually Earning Their Keep
The most successful deployments right now aren’t flashy. They’re unglamorous, high-volume, rules-heavy processes that were always painful for humans to do consistently:
Finance operations. Invoice matching, expense categorization, and vendor onboarding involve a lot of cross-referencing between systems that don’t talk to each other well. Agents handle the matching and flag exceptions instead of routing every single invoice through a person.
Customer support triage. Rather than replacing support agents outright, AI agents are increasingly used to read incoming tickets, pull relevant account history, draft a response, and hand the whole package to a human for a final check. This cuts resolution time significantly without removing the human from the loop entirely.
IT and DevOps monitoring. Agents watch system logs, correlate alerts across services, and open incident tickets with a first-pass root cause analysis already attached, so engineers start troubleshooting instead of searching.
Sales and account research. Before a rep even picks up the phone, an agent has already pulled firmographic data, recent news, and prior interaction history into a single briefing.
None of these use cases require a science-fiction level of autonomy. They require narrow, well-scoped agents with clear boundaries, which is exactly why the more successful implementations tend to come from teams that resist the temptation to build one giant, all-purpose agent.
The Governance Question Nobody Wants to Answer First
Here’s where a lot of otherwise well-planned agent projects stall: nobody decided in advance what the agent is allowed to do without a human sign-off. Should an agent be permitted to send an email to a customer without review? Approve a refund under $50? Modify a production database record?
Teams that skip this conversation tend to either over-restrict the agent until it’s barely useful, or under-restrict it until something goes wrong and trust collapses overnight. The teams that get it right treat permissions as a first-class design decision, not an afterthought bolted on after a pilot.
A practical approach looks like this:
-
Map every action the agent could plausibly take.
-
Classify each action by reversibility and financial or reputational risk.
-
Set explicit thresholds for autonomous action versus mandatory human approval.
-
Log everything, including the agent’s reasoning at each step, not just its final output.
This is also where working with a development partner that has actually shipped agentic systems in production pays off, because the failure modes are rarely obvious until you’ve seen a few of them firsthand.
A Realistic Timeline for Getting There
Teams often ask what the first ninety days of an agent rollout should actually look like. In practice, the successful ones follow a pattern that resists the urge to move fast on everything at once.
The first two to three weeks go entirely to process mapping, not model building. That means sitting with the people who currently do the work, documenting every decision point, and identifying which steps are genuinely rules-based versus which ones require judgment calls that are hard to codify. Skipping this step is the single most common reason agent projects underdeliver; the team ends up automating a process nobody fully understood in the first place.
Weeks four through eight typically involve building a narrow version of the agent that handles the highest-volume, lowest-risk slice of the workflow, running it in shadow mode alongside the human process so outputs can be compared without any real consequence if the agent gets something wrong. Only once accuracy stabilizes does the agent start taking live actions, usually starting with the lowest-risk category and expanding gradually.
By week twelve, the goal isn’t full autonomy. It’s a system with a track record, clear logs, and a known failure rate that the team is comfortable with. Expanding scope from there is far easier than trying to boil the ocean from day one.
What This Means for Teams Evaluating Vendors
If you’re scoping an agent project, the conversation with any potential partner should go well beyond model selection. Ask how they handle tool orchestration, how they test for hallucinated actions (not just hallucinated text), and how they design fallback paths when an agent gets stuck mid-task. A firm that can walk you through those specifics in concrete terms, rather than in marketing language, is worth far more than one with a longer feature list.
This is increasingly what separates a generic software vendor from a genuine AI Agent Development Services partner: the latter has already solved the boring, unglamorous reliability problems that make agents trustworthy enough to run without constant supervision.
Frequently Asked Questions
What’s the difference between an AI agent and an AI assistant?
An assistant responds to prompts. An agent can plan a sequence of actions, call external tools, and evaluate its own results with limited or no human input at each step.
Are AI agents safe to use for financial transactions?
Only within carefully defined limits. Most production deployments cap autonomous financial actions at a low dollar threshold and require human approval above it.
How long does it take to deploy an enterprise AI agent?
A narrow, well-scoped agent for a single process can often go from pilot to production in six to twelve weeks. Broader, multi-system agents take longer because of the integration and governance work involved.
The Bottom Line
Agentic AI isn’t a future trend anymore; it’s already running inside finance teams, support desks, and IT departments at companies that decided to start with a narrow, well-governed use case instead of an ambitious one. Firms that treat agent permissions and observability as core design work, not an afterthought, are the ones seeing real time savings without the horror stories. For companies weighing whether to build this internally or bring in outside expertise, the deciding factor usually isn’t the model. It’s whether the team has actually shipped something like this before, in production, under real operational pressure.