Snowflake Stored Procedures vs User-Defined Functions
Stored Procedures and User-Defined Functions in Snowflake serve different purposes. Learn their key differences, use cases, syntax, and when to use each.
 Arnika
When working with Snowflake, SQL is not always limited to simple SELECT, INSERT, or UPDATE statements. As data pipelines become more complex, developers often need reusable logic for calculations, validations, transformations, and automated operations. This is where Snowflake Training in Chennai introduces two important concepts: Stored Procedures and User-Defined Functions (UDFs).
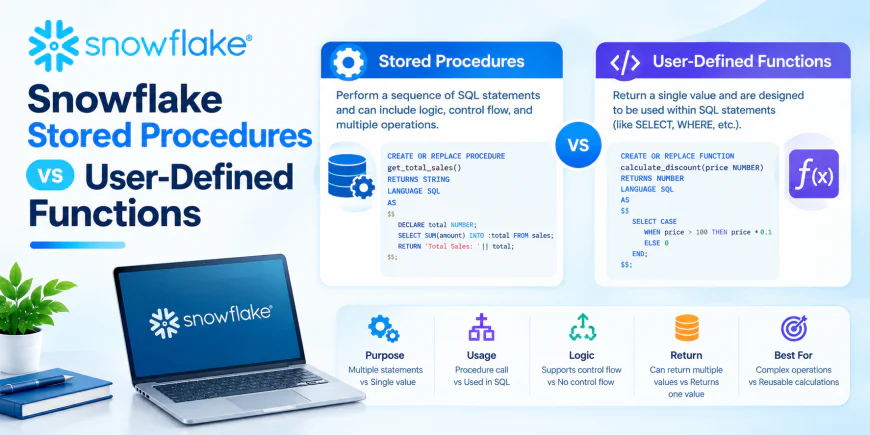
Although both allow you to create reusable logic, they are designed for different purposes. A Stored Procedure is mainly used to perform a sequence of operations, while a User-Defined Function is generally used to calculate or return a value. Understanding this difference helps you choose the right option when developing Snowflake applications and data pipelines.
What Is a Stored Procedure in Snowflake?
A Stored Procedure is a reusable piece of code stored inside Snowflake. It can contain multiple statements and can perform operations such as inserting data, updating tables, deleting records, or executing other SQL statements.
For example, suppose a data pipeline needs to:
-
Read data from a staging table.
-
Validate the records.
-
Update the target table.
-
Insert new records.
-
Log the processing status.
Instead of writing these operations separately every time, you can place the logic inside a Stored Procedure and call it when required.
A simple procedure can look like:
CREATE OR REPLACE PROCEDURE process_customer_data()
RETURNS STRING
LANGUAGE SQL
AS
$$
BEGIN
INSERT INTO customer_target
SELECT *
FROM customer_stage;
RETURN 'Customer data processed successfully';
END;
$$;
The procedure can then be executed with:
CALL process_customer_data();
The important point is that a Stored Procedure is designed to perform an action or workflow.
What Is a User-Defined Function?
A User-Defined Function, commonly called a UDF, is a custom function created by the developer to perform a specific calculation or transformation.
You can pass values to a UDF, process them, and return a result.
For example, suppose you frequently need to convert a customer's name to uppercase.
You could create:
CREATE OR REPLACE FUNCTION format_name(name STRING)
RETURNS STRING
LANGUAGE SQL
AS
$$
UPPER(name)
$$;
Then use it inside a query:
SELECT format_name(customer_name)
FROM customer;
Here, the function takes an input and returns a value.
That is the key idea behind a UDF: take input, perform logic, and return a result.
Stored Procedure vs UDF: The Basic Difference
The easiest way to remember the difference is:
Stored Procedure → Performs an operation
UDF → Returns a value
Imagine a customer data pipeline.
A UDF could calculate the customer's age, classify the customer, format an email address, or calculate a discount.
A Stored Procedure could handle the entire process of loading customer data from staging into the target table.
So, even though both are reusable database objects, their responsibilities are different.
When Should You Use a Stored Procedure?
Stored Procedures are useful when you need to perform multiple steps as part of a process.
For example, consider a daily sales pipeline:
Source Data
↓
Staging Table
↓
Validation
↓
Transformation
↓
Target Table
↓
Audit Logging
This workflow may require several SQL statements. Instead of manually executing every statement, a Stored Procedure can contain the complete processing logic.
They are particularly useful for:
-
Data loading workflows
-
ETL or ELT operations
-
Data validation
-
Multiple SQL statements
-
Error handling
-
Audit logging
-
Administrative operations
-
Automating repeated database tasks
Stored Procedures can also contain procedural logic such as variables, conditional statements, and loops when supported by the selected procedure language.
When Should You Use a UDF?
UDFs are a better choice when you have a reusable calculation or transformation that needs to be used inside SQL queries.
For example, you may have a business rule that calculates a customer's category:
CREATE OR REPLACE FUNCTION customer_category(amount NUMBER)
RETURNS STRING
LANGUAGE SQL
AS
$$
CASE
WHEN amount >= 100000 THEN 'Premium'
WHEN amount >= 50000 THEN 'Gold'
ELSE 'Regular'
END
$$;
You could then use the function directly in a query:
SELECT
customer_id,
customer_category(total_amount) AS category
FROM customer_sales;
This makes the business rule reusable instead of repeating the same CASE expression across multiple queries.
Can a UDF Modify a Table?
This is an important distinction.
A UDF is primarily designed to return a value and is generally used within expressions in SQL statements. It should not be treated as a replacement for a Stored Procedure when you need to perform database operations such as updating or inserting rows.
For example, if your requirement is:
“Calculate the total price after applying a discount.”
A UDF is a good fit.
If your requirement is:
“Load today's records, update existing rows, insert new rows, and write an audit entry.”
A Stored Procedure is more appropriate.
Stored Procedures and UDFs With Different Languages
Snowflake supports different implementation options for Stored Procedures and UDFs, depending on the requirement.
SQL can be used for straightforward database logic. Snowflake also supports languages such as JavaScript and Python for supported procedural and function use cases.
This gives developers flexibility when SQL alone is not enough.
For example, a simple transformation can often be handled with a SQL UDF, while more complex application-style processing may benefit from a procedure written using a supported procedural language.
The important thing is not to choose a language simply because it is available. Start with the business requirement and select the simplest approach that handles it effectively.
A Practical Example
Consider an employee data warehouse.
The company receives employee records every day.
A UDF might calculate an employee's salary band:
Salary
↓
UDF
↓
Salary Band
For example:
50000 → Standard
80000 → Premium
120000 → Executive
A Stored Procedure, on the other hand, could manage the complete daily load:
Employee Source
↓
Employee Staging
↓
Validation
↓
MERGE
↓
Employee Target
↓
Audit Log
The two objects can even work together. A UDF can handle a specific calculation while a Stored Procedure manages the larger data-processing workflow.
Common Mistakes When Choosing Between Them
One common mistake is using a Stored Procedure for every small calculation. If the requirement is simply to transform an input value and return a result, a UDF may be cleaner.
Another mistake is expecting a UDF to behave like a complete data pipeline. When multiple database operations need to happen in sequence, a Stored Procedure is usually a better fit.
It is also worth considering maintainability. If the same business rule appears in many queries, placing that logic inside a UDF can reduce duplication.
For larger workflows, keeping processing logic inside a Stored Procedure can make automation and maintenance easier.
Stored Procedures vs UDFs: Which One Should You Choose?
Think about what you want the object to do.
If you need to execute a process, choose a Stored Procedure.
If you need to calculate or transform a value, consider a UDF.
For example:
Need to calculate a value?
↓
UDF
Need to execute multiple operations?
↓
Stored Procedure
This simple distinction can help avoid a lot of confusion when designing Snowflake solutions.
Final Thoughts
Stored Procedures and User-Defined Functions both help make Snowflake development more organized and reusable, but they solve different problems. A Stored Procedure is better suited for workflows and database operations, while a UDF is useful for reusable calculations and transformations.
Once you understand where each one fits, you can design cleaner SQL code, reduce repeated logic, and build more maintainable data pipelines. Practical exposure to SQL, procedures, functions, data loading, and real-world workflows makes these concepts much easier to understand. Qmatrix Technologies focuses on hands-on Snowflake learning so these database concepts can be connected to practical data engineering scenarios rather than being treated as theory alone.